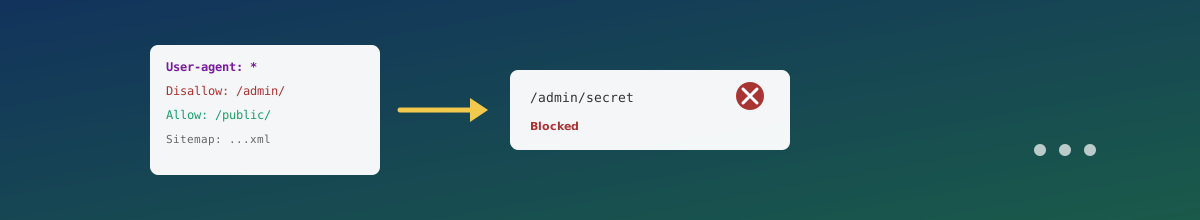
Paste a robots.txt (or fetch one from a live domain) and test whether a path is allowed or blocked for a given user-agent — using the same most-specific-group and longest-match-wins rules search engines follow. Parsing and matching run entirely in your browser; fetching a live domain's robots.txt is the one part that has to go through this server.
curl -sS -X POST https://devops.majbase.com/robots-txt-tester/api -H "Content-Type: application/json" \
  -d '{"robots_txt":"User-agent: *\nDisallow: /admin/","user_agent":"Googlebot","path":"/admin/page"}'
Returns {"groups", "sitemaps", "allowed", "matched_rule", "matched_user_agent"}, or {"error": "..."}.
Want an AI agent (Claude Code, claude.ai, or anything else that supports the Agent Skills format) to use this tool for you on request? Download the skill below and add it:
~/.claude/skills/robots-txt-tester/SKILL.md