Forecast vs. Actual
Back to Performance Tuning and Capacity Planning · Scheduled Cadence · Cost-Aware Scaling · Feeds Back Into Tuning · Service Offerings
Comparing prior projections against what really happened, so future forecasts keep getting more accurate. Most capacity planning produces forecasts and never scores them, which means the same error is repeated indefinitely without anyone being able to name it.
1. Record the Forecast So It Can Be Scored
A forecast that lives in a slide cannot be checked later. To be scorable it needs four things written down at the time it is made:
- The metric, precisely. “Database load” is not scorable; “peak hourly write transactions” is.
- The number and the date it applies to.
- The method — which window the trend came from, which growth model, from trend-based projections.
- The assumptions: the clients, launches and campaigns it already includes. Without these, a miss cannot be separated from a change of plan.
2. Read the Direction Before the Size
A single miss tells you almost nothing. The pattern across several periods tells you a great deal, and the first thing to look at is the sign.
- Errors scattered either side of zero are noise. The method is sound and the spread is your honest uncertainty — widen the band, do not change the model.
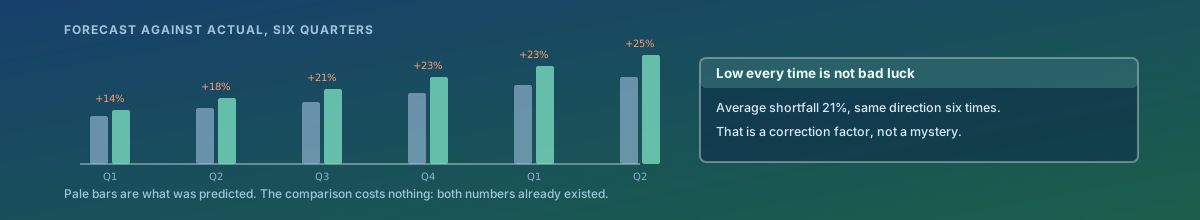
- Errors consistently in one direction, as in the illustration above, are a bias. Six quarters low, averaging 21 per cent, is not a run of bad luck. It is a correction factor sitting in plain view.
- Errors growing over time mean the model's shape is wrong — usually a linear fit against something that is compounding.
3. Find the Cause Before Applying the Factor
Multiplying every forecast by 1.21 would fix the arithmetic and hide the reason. Consistent under-forecasting usually has one of a few specific causes, and each has a different fix:
- Per-user load grows alongside user count. More users means more data, which makes every query slower, so load grows faster than the user curve. This is the most common one and it is why linear projections drift low.
- Only planned work is counted. Unplanned clients, integrations and features are a real and fairly steady contribution, and excluding them biases every forecast the same way.
- Averages are forecast where peaks are what matter. Peak-to-average ratios tend to worsen with growth, not hold.
- Retired load is assumed. The old system that was supposed to be switched off usually is not, on schedule.
4. Separate a Bad Forecast From a Changed World
If a client twice the size of any previous one signed mid-quarter, the forecast was not wrong — its inputs changed. Recording the assumptions is what makes this distinction possible afterwards, rather than a matter of memory and argument.
Score the two separately. Forecast error measured against the original assumptions tells you about the method. Deviation caused by new inputs tells you how volatile your pipeline is, which is its own useful number and belongs in scenario modeling.
5. What To Do With the Result
- Adjust the model where the cause is understood — switch to a compounding fit, include a term for unplanned work, forecast peaks instead of means.
- Widen the band where the cause is genuine uncertainty. A forecast range that has been right 80 per cent of the time is more useful than a point estimate that is always wrong by an unknown amount.
- Shorten the horizon if accuracy collapses beyond a certain distance. Say so explicitly rather than publishing a two-year number nobody should rely on.
- Pull the trigger points in — a method known to run low should act at a higher headroom than one known to be accurate.
6. Keep the History
After four or five periods this becomes a short table that answers the question every capacity request eventually meets: how good are these numbers, historically? A planner who can answer “we have been within 10 per cent five quarters running” is in a different negotiation from one who cannot answer at all.
It also catches the opposite failure. Forecasts that are always high are quietly expensive, and nothing else in the process will find them — see cost-aware scaling.
How We Approach It
- Write forecasts in a scorable form: metric, number, date, method, assumptions.
- Score each one when its date arrives, as a standing item in the scheduled review.
- Look at the sign before the magnitude, over several periods.
- Attribute the error to the method or to changed inputs, using the recorded assumptions.
- Fix the cause rather than applying a blanket multiplier.
- Keep the accuracy history and publish it with the next forecast.
What You Get
- Forecasts recorded in a form that can be checked later.
- A scoring step in the review cycle, so errors are noticed rather than forgotten.
- Bias separated from noise, and method error separated from changed inputs.
- A stated accuracy history that gives your next capacity number some standing.
The question worth asking: of the last four capacity forecasts, how many were checked against what actually happened?