Cost-Aware Scaling
Back to Performance Tuning and Capacity Planning · Scheduled Cadence · Forecast vs. Actual · Feeds Back Into Tuning · Service Offerings
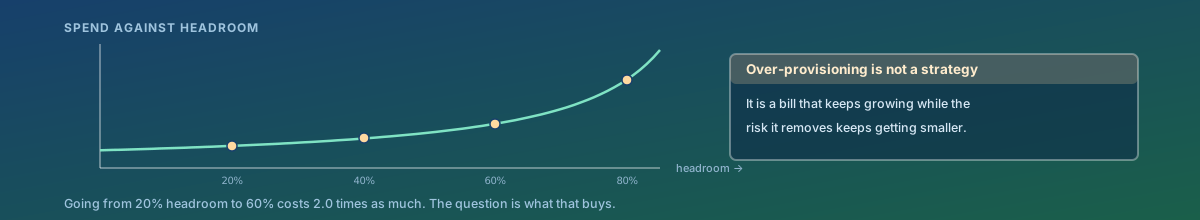
Balancing headroom against spend, since “just over-provision everything” is not a real capacity strategy. It is a bill that keeps growing while the risk it removes keeps getting smaller — and the growth is not linear.
1. The Shape of the Curve
To carry a load at a given headroom you need capacity equal to the load divided by the fraction you are willing to use. That one over the remaining margin is what produces the curve above.
- 20 per cent headroom means running at 80 per cent: 1.25× the load in capacity.
- 60 per cent headroom means running at 40 per cent: 2.5× the load.
- So moving from 20 to 60 per cent headroom costs exactly twice as much, and 80 per cent headroom costs four times the 20 per cent figure.
Below roughly half, extra headroom is cheap and worth buying without much analysis. Past that the curve turns, and each further slice costs more than everything before it. That bend is where the decision actually lives.
2. Headroom Is Not One Number
A single organisation-wide target is almost always wrong in both directions at once. The right target per resource depends on how fast that resource can be added and how badly it fails when exhausted.
- Resources that scale in minutes — stateless application instances behind an autoscaler — need only enough headroom to cover the scaling delay plus the arrival rate during it. Often 20 to 30 per cent.
- Resources with a long lead time — a database primary, physical hardware, a licensed tier — need headroom covering the whole provisioning period, which lead-time awareness quantifies. This is where 50 per cent and more can be justified.
- Resources that fail abruptly — disk, memory, connection pools, file handles — need more margin than those that degrade gracefully, because there is no warning region to react in.
- Resources whose exhaustion is merely slow can run tighter, as long as somebody owns the latency that results.
3. Price the Buffer Against What It Prevents
Headroom is insurance, and insurance is priced against the loss. Both sides of this can be estimated well enough to decide with.
- The premium is the annual cost of the extra capacity — a figure the cloud bill or the purchase order already contains.
- The loss is the cost of an hour of degradation or outage: lost transactions, contractual credits, the staff hours spent, and the slower-moving reputational cost.
- The frequency is how often the tighter setting would have been exceeded, which your own history can answer directly. Replay last year's peaks against the proposed threshold rather than guessing.
This turns an argument about caution into an arithmetic comparison, and it occasionally shows that the current buffer is far larger than anything the loss would justify.
4. Cheaper Headroom Than Buying More
Before paying the price on the curve, check whether the same margin is available at a lower one. The alternatives are frequently cheaper by an order of magnitude:
- Tuning. An index that halves the dominant query doubles the headroom at no recurring cost — see slow query identification.
- Caching, which removes load rather than absorbing it; see caching strategy.
- Shedding and degradation. A system that can drop non-essential work under pressure survives a peak that would otherwise require permanent capacity to meet — see breaking point identification.
- Moving work off the peak. Batch jobs, reports and imports scheduled into the quiet hours lower the peak itself, which is the number the whole curve is scaled by.
- Faster provisioning. Cutting the lead time cuts the required buffer directly, and is often a process change rather than a purchase.
5. Scaling Down Is Part of It
Capacity reviews that only ever add are a ratchet. Load genuinely falls — a client leaves, a feature is retired, an optimisation lands — and the capacity provisioned for it usually stays.
- Look for resources whose utilisation has fallen for several consecutive periods.
- Look for the over-provisioning that followed the last incident, which was correct at the time and may not be now.
- Reduce in steps, with the measurement in place to catch it if the reduction was wrong.
- Where forecasts are consistently high, every one of them has been paid for — see forecast vs. actual.
6. Commitment and Elasticity
On metered infrastructure the unit price depends on how it is bought, and the two choices interact with the curve above.
- Commit to the floor, not the peak. Reserved or committed capacity is cheaper per unit, and the safe amount to commit is the load that is present even in the quietest week.
- Buy the peak elastically, accepting the higher unit price for the hours you actually need it. The arithmetic favours this whenever the peak lasts a small fraction of the month.
- Check the elasticity is real. Autoscaling that cannot act faster than the load arrives is paying the elastic price for fixed capacity.
How We Approach It
- Set a headroom target per resource, derived from its lead time and its failure behaviour, not one number for everything.
- Put a price on the current buffer and on an hour of the outage it prevents.
- Replay historical peaks against the proposed thresholds, so frequency is measured rather than assumed.
- Exhaust the cheaper headroom first — tuning, caching, shedding, off-peak scheduling, shorter lead times.
- Review downwards as well as upwards, in steps, with measurement.
- Commit the floor and rent the peak, after verifying the elasticity responds fast enough to matter.
What You Get
- Per-resource headroom targets with a stated reason for each.
- The cost of the current buffer and the cost of the risk it covers, side by side.
- A list of the cheaper ways to buy the same margin, priced against buying capacity.
- A scale-down review, so provisioning is not a one-way ratchet.
The question worth asking: what is the current headroom costing per year, and when was that number last compared with what it prevents?