Per-Resource Runway
Back to Performance Tuning and Capacity Planning · Trend-Based Projections · Lead-Time Awareness · Scenario Modeling · Service Offerings
Separate forecasts for CPU, memory, storage, and database capacity, since they rarely run out at the same time. A single figure for “how much headroom we have” is the average of four unrelated numbers, and it describes none of them.
1. Two Things Differ, Not One
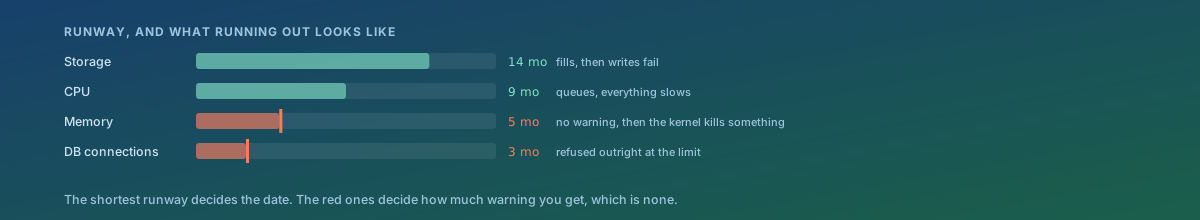
The obvious difference is length: the shortest runway sets the date, and in the illustration above that is three months while the longest is fourteen. Forecasting the one with the most history, or the one easiest to graph, answers the wrong question.
The less obvious difference is what running out looks like, and it changes where the warning line belongs.
| Resource | Approaching the limit | At the limit |
|---|---|---|
| CPU | Degrades smoothly. Queueing grows, latency rises, and the shape is visible for weeks | Everything slow, nothing broken |
| Storage | Nothing at all until near the end, then fragmentation and copy-on-write overhead bite | Writes fail, which for a database usually means it stops |
| Memory | Nothing. Linux uses what is free for cache, so a healthy machine and a nearly-full one look alike | Swapping, then the kernel kills a process you did not choose |
| Database connections | Nothing | Refused outright, instantly, at the limit |
Two of these give a gradual signal and two give none. For the second kind, the forecast is the warning system, because nothing else will provide one.
2. Set the Threshold From the Failure Mode
- CPU — plan from sustained peak rather than average, and leave room for the loss of one instance. Eighty per cent across two nodes becomes 160 across one.
- Storage — treat the usable limit as well below full. Many filesystems slow markedly in the last tenth, and a copy-on-write filesystem or a database needing room to rewrite needs considerably more than that.
- Memory — forecast the working set, not free memory, which on Linux is not a useful number. Swap-in rate is the leading indicator and it appears late.
- Connections — forecast the total across every pool, which is arithmetic rather than a trend. See connection pool sizing.
3. The Resources People Forget Entirely
The four above are the ones with graphs. These have limits too, and reaching one looks exactly like an outage:
- Inodes. A disk with free space that cannot create a file.
- Database identifier ranges. A 32-bit primary key at two billion rows, and transaction identifier wraparound in PostgreSQL, which arrives with no warning if autovacuum has been failing quietly.
- IP addresses in a subnet, which container platforms consume far faster than anyone plans for.
- Backup window. A backup that takes seven hours in a six-hour window has run out of a resource that nobody was tracking.
- Licence counts and API quotas, which fail as hard as any disk.
4. Runway Is Not a Property of the Resource
The same resource has different runways depending on what you count as the limit, and the one to use is the point at which behaviour becomes unacceptable rather than the point of failure.
A disk is full at 100 per cent and unusable somewhat earlier. A database is at its limit at its configured maximum and unhealthy below it. CPU is exhausted at 100 per cent and your latency target was breached well before. Forecast to the figure your users would notice.
5. One Number Per Resource, Reviewed Together
Each resource gets its own forecast; the review looks at all of them at once. That is what surfaces the useful pattern — two resources running out within a month of each other is one project rather than two, and worth coordinating.
It also surfaces the opposite: a resource with a fourteen-month runway does not need attention, and saying so is as valuable as raising the alarm on the three-month one.
How We Approach It
- Forecast each resource separately, including the ones without a dashboard: inodes, identifier ranges, addresses, backup window, quotas.
- Set each threshold from its failure mode, not uniformly, so the cliff-edge resources are warned about earlier.
- Use the figure that matters — sustained peak for CPU, working set for memory, total across pools for connections.
- Include the loss of one instance wherever capacity is shared across several.
- Rank by runway and name the binding one.
- Hand the dates to lead-time awareness, since a runway is not yet a decision date.
What You Get
- A runway per resource, in months, with the binding one named.
- A threshold for each derived from how it fails, so the ones with no early warning get an earlier line.
- The unglamorous limits included, which is usually where the surprise is.
- Redundancy accounted for, so a runway is not quietly assuming every node stays up.
- The resources that need nothing said so explicitly.
The question worth being able to answer: which resource runs out first, and would you get any warning before it did? For two of the four, the answer to the second part is no.