Connection Pool Sizing
Back to Performance Tuning and Capacity Planning · Kernel and Filesystem Parameters · Caching Strategy · Before-and-After Measurement · Service Offerings
Database and HTTP connection pools sized to match real concurrency, avoiding both starvation and wasted overhead. Both failures are real, they look similar from the outside, and the remedy for one makes the other worse — which is why this is worth measuring rather than guessing.
1. The Curve Has a Peak
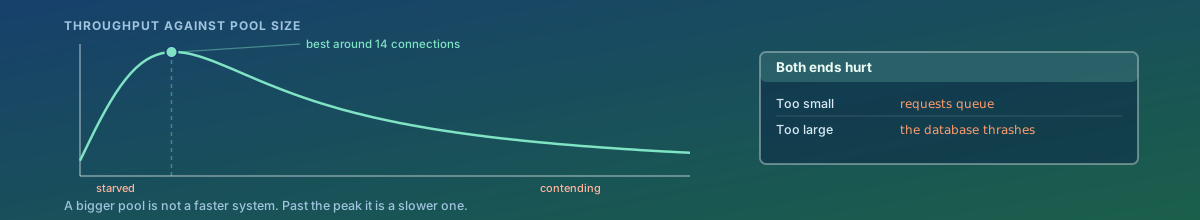
Throughput against pool size is not a rising line. It rises, peaks, and falls, as in the illustration above, and the fall is not gentle.
- Below the peak the pool starves. Requests wait for a connection that is busy. The database is not loaded; your application is queueing in front of it.
- Above the peak the database contends. More concurrent queries than it has cores or disk to serve means context switching, lock contention and cache pressure. The same work takes longer because it is all happening at once.
The practical consequence is counter-intuitive and worth stating plainly: when a system is slow under load, enlarging the pool is the usual reaction and is frequently the wrong direction.
2. The Right Size Is Smaller Than People Expect
A database executes queries on CPUs and disks it actually has. Concurrency beyond that is queueing with extra overhead, and the useful number is driven by the server's resources rather than by your traffic.
Little's law gives the sanity check without any benchmarking. Required concurrency equals arrival rate multiplied by service time: 500 queries per second averaging 4 ms is 500 × 0.004, or two connections busy at any instant. A pool of 100 for that workload is 98 idle connections, each still costing memory on the database and a slot against its limit.
Start from a figure in the region of the database's core count rather than from the number of application threads, then measure.
3. Pools Multiply, and the Limit Is Shared
The arithmetic that produces outages: a pool of 50 looks modest until the service runs eight instances, and then it is 400 connections against a database configured for 200. Nothing is wrong with any single configuration.
- Count pools, not instances. Multiply by replicas, and include the ones nobody remembers — batch jobs, migrations, admin tools, monitoring.
- Leave headroom for the connections you did not plan: a human with a client open, a backup, a replication slot.
- Autoscaling multiplies the pool too. A service that scales to twenty instances under load opens twenty pools at exactly the moment the database is busiest.
- Where the total genuinely must be high, a connection proxy in front of the database is the structural answer, letting many application connections share far fewer real ones.
4. The Timeout Decides What Saturation Looks Like
When the pool is exhausted, the acquisition timeout decides whether you get a slow system or a failing one. Both are bad; one is recoverable.
- No timeout, or a long one, and requests pile up until the application runs out of threads. The failure spreads from one dependency to the whole service.
- A short timeout fails the request quickly, which is unpleasant and contained, and makes the cause obvious in the logs.
- Set it shorter than the caller's own timeout, otherwise the client has already given up and you are doing work for nobody.
- Watch acquisition wait time, not just pool usage. A pool at 100 per cent with no wait is correctly sized. A pool at 70 per cent with waits is not.
5. Connections Held Longer Than the Query
A pool exhausts at a fraction of its nominal capacity when connections are held across work that is not database work. The common patterns:
- A transaction opened at the start of a request handler and held through an external API call.
- A connection acquired before a slow computation and used after it.
- A long-running report on the same pool as interactive traffic, where one query holds a connection for a minute.
Each of these is fixed in the application rather than by sizing, and each makes the pool look too small when it is not. Separate pools for interactive and batch work solve the last one outright.
6. HTTP Pools Fail Differently
Outbound HTTP pools have the same shape and one extra failure: a pool too small for a slow remote service turns someone else's latency into your outage. The remote call takes two seconds, your pool holds ten connections, and above five requests per second everything queues.
Size against the remote service's actual latency rather than its advertised one, keep separate pools per destination so one slow dependency cannot starve the others, and set a timeout that is shorter than your own response deadline.
How We Approach It
- Measure real concurrency — arrival rate and service time — rather than starting from thread counts.
- Count every pool against the database limit, including replicas, batch jobs and tooling, and compare the total to what the server allows.
- Find the peak by testing, at several sizes under representative load, since the curve's shape is specific to your queries and hardware.
- Check for connections held longer than their queries, which is a code problem that sizing cannot fix.
- Set timeouts that fail fast and inside the caller's deadline, and separate interactive traffic from batch.
- Instrument acquisition wait time, which is the metric that tells you the pool is wrong, and alert on it.
What You Get
- A measured concurrency requirement, and a pool size derived from it rather than chosen.
- The total connection count across every pool against the database's limit, with the ones nobody was counting included.
- Throughput measured at several pool sizes, so the peak is known rather than assumed.
- Timeouts that fail fast and within the caller's deadline, and batch work separated from interactive.
- Acquisition wait time instrumented and alerted, which is the early warning that sizing is drifting out of date.
The question that settles most arguments about this: at peak, how long does a request wait to get a connection? If the answer is zero, the pool is not your problem however small it looks.