Scheduled Maintenance Calendar
Back to Data Center Management · Warranty Tracking · Spare Parts Management · Escalation Contacts · Service Offerings
This is vendor visits and firmware work planned into low-impact windows. It is the facility counterpart to scheduled maintenance, which covers patching and the software side of keeping systems current. The distinction matters because this work has a different rhythm: it is annual or quarterly rather than monthly, it is performed by people who do not work for you, and it has to be booked weeks ahead.
1. What Belongs on It
- Cooling plant service — filters, coils, refrigerant, condensate, typically on a quarterly or semi-annual cycle.
- UPS maintenance and battery testing. Battery strings are consumable and have a service life measured in a few years, which means there is a replacement date to plan for rather than a failure to wait for.
- Generator exercise and load bank testing. Running a generator unloaded proves it starts; it does not prove it can carry the building. A load bank test is the one that answers the question you actually care about.
- Fire detection and suppression inspection, usually annual and usually a legal requirement.
- Electrical inspection and thermographic survey, which finds the loose connection that becomes a fault.
- Firmware and BIOS on servers, switches, storage, PDUs and the management controllers that nobody updates until there is an advisory.
- Vendor site visits under the contracts tracked in warranty tracking, many of which are preventive visits you have already paid for and may not be taking.
2. The Real Risk Is Two Windows Overlapping
Each of these is routine on its own. The hazard is in the combination, and it is the reason to keep one calendar rather than several.
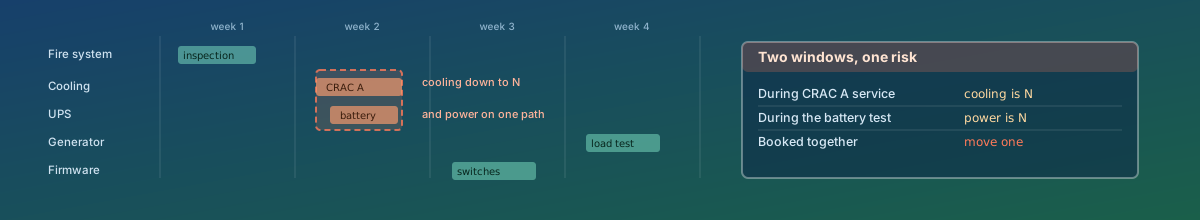
During a cooling unit service the room is running at N rather than N+1. During a UPS battery test, part of the power path is unavailable. Each is an accepted, time-boxed reduction. Booked into the same window — which happens easily, because two different vendors each proposed a convenient Tuesday — the room has no cooling redundancy and no power redundancy simultaneously, and a single further fault becomes an outage.
So the calendar needs to express, for each window, what redundancy is reduced and to what level. That makes the clash in the illustration above visible when it is booked, rather than on the day. The capacity figures behind it come from cooling capacity and power circuit headroom.
3. Declaring the Reduced Period
- State it in advance, to whoever carries risk: on-call, service owners, and customers where an agreement requires notice.
- Avoid stacking other change on top. A maintenance window is a poor time for an unrelated deployment, because diagnosis becomes ambiguous the moment two things changed.
- Know the rollback. Firmware in particular: what happens if the update fails halfway, and whether the device can be recovered without a site visit.
- Have the escalation path open. If a vendor's engineer breaks something at 22:00, the route to their senior support is the one in escalation contacts, and it should be in hand before the window rather than looked up during it.
4. Choosing the Window
- Low impact is not the same as out of hours. Out of hours is when fewest people are watching, which is a real cost for work that can go wrong. For anything with a meaningful failure mode, a quiet weekday with the full team available is often the better choice.
- Avoid the obvious peaks, and define freeze periods once rather than arguing about them each time — month end, a retail season, an audit period.
- Respect vendor lead times. Specialist engineers and load banks are booked weeks ahead, and a window chosen without checking availability is a window that moves.
- Leave room for overrun. Work that is planned to fill the entire window has no margin, and the decision to abandon halfway is much harder than the decision not to start.
5. The Part Everyone Skips: Recording the Outcome
The engineer leaves, the system works, the ticket closes. What was found is lost, and that is the most valuable output of the visit.
- What was actually done, against the asset tag.
- What was found but not fixed — a worn part, a reading out of range, a recommendation. These accumulate into the picture that trending cannot see.
- Parts replaced, and whether your spares were consumed.
- Whether it overran, which is how next year's window gets planned honestly.
- The next due date, scheduled before the engineer leaves rather than remembered later.
How We Approach It
- Collect every maintenance obligation — contractual, statutory and sensible — including the preventive visits already paid for and not being used.
- Put them on one calendar, with owner, vendor, lead time and frequency.
- Annotate each with the redundancy it reduces, so clashes are visible at booking time.
- Define freeze periods and the preferred window type per class of work.
- Agree the notification and the rollback position for anything that can fail badly.
- Establish the record: what was done, what was found, what was deferred, and the next due date set before the visit closes.
What You Get
- One calendar covering facility, vendor and firmware work, with frequencies and lead times.
- Each window annotated with the redundancy it removes, and the clashes in the current plan identified.
- Freeze periods and window conventions agreed once rather than negotiated per job.
- A notification and rollback position for the work that can go wrong.
- A maintenance record that captures findings and deferrals, not just completion.
The question that justifies the calendar: if a cooling unit is being serviced this Thursday, does anyone know, and is anything else scheduled against the same window?