Vendor Escalation Contacts
Back to Data Center Management · Warranty Tracking · Scheduled Maintenance Calendar · Spare Parts Management · Service Offerings
This is a clear path to the right vendor contact when something needs faster attention than the standard queue. It is the outward-facing half of escalation path, which covers how an incident travels inside your own organisation. Both exist for the same reason: at the moment you need the route, nobody has time to work out what it is.
1. The Standard Queue Is Built for the Average Case
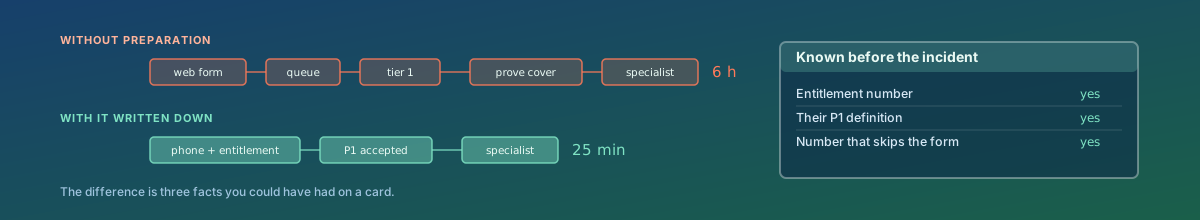
A vendor's front door — the web form, the general number, the shared mailbox — is designed for the volume of ordinary requests, and it works well for them. An outage is not an ordinary request, and routing it through the ordinary path costs hours in triage before anyone competent to help has seen it.
The difference between the two routes in the illustration above is not a relationship or a premium contract. It is a handful of facts that were either written down beforehand or were not.
2. What to Have Written Down, Per Vendor
| Item | Why it changes the outcome |
|---|---|
| Contract and entitlement numbers | The first thing asked, and the commonest delay. Failing an entitlement check puts an outage into the unsupported queue. Sourced from warranty tracking |
| The number that reaches a human | Many vendors have a priority line for contract holders that is not the one on the website |
| Their severity definitions | Vendors define severity narrowly and by their own wording. See section 3 |
| Account or technical account manager | A named person with internal reach, who is useful before the incident as well as during it |
| The escalation ladder | Who to ask for when the case is open and nothing is happening — duty manager, escalation manager, and what triggers each |
| Out-of-hours arrangements | Whether the night team is the same team, in which region, and in which language |
3. Severity Is Their Definition, Not Yours
Every vendor publishes severity levels, and the top one is usually defined tightly: production down, no workaround, business materially stopped. A case that genuinely meets it will be treated very differently from one that does not.
- Read their definitions in advance and know which of your scenarios qualify.
- Describe the impact in their terms. "The cluster is degraded" invites a lower severity than the same situation described as production unavailable with no workaround — when that is true.
- Do not inflate. A vendor that has seen three false P1s from you will treat the fourth accordingly, and they are right to.
- Know the de-escalation rule, because a P1 usually obliges you to stay available continuously too.
4. An Untested Path Is a Hypothesis
Every link here can be silently broken for a year: a decommissioned number, an entitlement that did not transfer at renewal, an account manager who left, a portal login tied to someone who has also left.
- Call the priority number during business hours and confirm your entitlement is recognised. Entitlement lookups failing is extremely common and always discovered at the worst time.
- Check the portal logins work and are not personal accounts belonging to one individual.
- Confirm the named contacts still exist, on a review cycle. Vendor staff turnover is high.
- Record how long it actually took to reach someone competent. That number is an input to your recovery planning, and it is usually worse than assumed.
5. Reachable When Things Are Broken
The list has to be available during exactly the conditions that make systems unavailable.
- Not only in a wiki hosted on the infrastructure that might be down.
- Not only in a password manager that needs the network.
- A printed copy in the room, and one on the phones of whoever is on call — the same argument made for out-of-band documentation.
- Include the facility provider's own emergency number and remote hands line, which are the ones you need when you cannot get to the building.
6. Keep It Small and Owned
A contact list grows until nobody trusts it. Keep one entry per vendor that matters, give it an owner, review it on a schedule, and delete vendors you no longer use. A short list that is right beats a comprehensive one that is half wrong, because during an incident nobody can tell which half they are reading.
Record alongside each entry when it was last verified. An undated contact list is indistinguishable from an abandoned one.
How We Approach It
- Identify the vendors that matter — the ones whose failure stops something.
- Collect the facts per vendor: entitlement, priority number, severity definitions, named contacts, escalation ladder, out-of-hours arrangement.
- Test each path during business hours, including the entitlement check, and record what actually happened.
- Publish it where it survives an outage, including on paper.
- Connect it to your internal escalation, so it is clear who is authorised to raise a severity-one case and commit to the obligations that come with it.
- Set a review cadence with dated verification.
What You Get
- One page per vendor with entitlement, the number that works, severity definitions and named contacts.
- Each path tested, with the measured time to reach someone who could help.
- A list that survives the outage it exists for, including on paper in the room.
- Clear authority over who raises a severity-one case, tied to your internal escalation.
- Dated verification, so the list's age is visible rather than assumed.
The honest test: pick your most critical vendor and find the number you would call tonight. If that takes more than a minute, the list is the deliverable.