A Backup You Have Never Restored Is Not a Backup
Updated: October 5, 2026 (7531-10-15 in the Bulgarian calendar)
Back to Strategic Approach · Backup and Recovery · Disaster Recovery Planning · Service Offerings
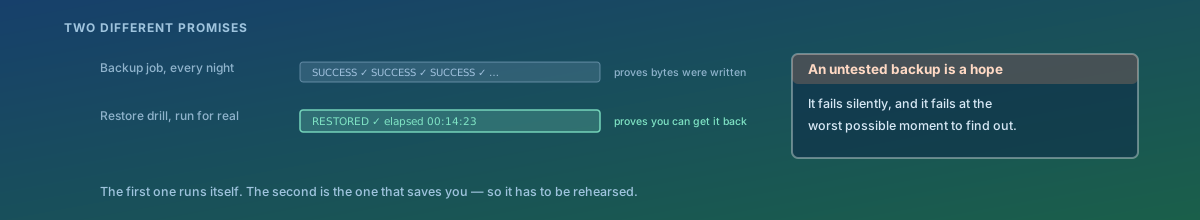
A backup job that reports success proves one thing: that bytes were written somewhere. It does not prove you can get your data back. Those are two different promises, and the gap between them is exactly where organisations discover — at the worst possible moment — that what they had was a hope, not a backup. This is one of the two areas where we are least flexible, because it fails silently and it fails under pressure.
1. Why Backups Fail Silently
A failing backup rarely announces itself. The job runs, the log says SUCCESS, the dashboard is green, and everyone moves on — for months or years — until a restore is needed and the quiet failure surfaces all at once.
- Success means “the job finished,” not “the data is usable.” A dump can complete while silently excluding a table; an image can be written while the volume it needed was unmounted; a file can copy perfectly while being corrupt at the source.
- The thing that breaks is often downstream of the job. A full disk, an expired credential, a rotated encryption key, a changed schema — none of these trip the backup job, and all of them can make the restore impossible.
- Nobody looks until it is too late. The only event that reliably checks a backup is a real disaster, which is the one occasion when you cannot afford for the check to fail.
2. The Two Different Promises
The illustration above is the whole argument. The nightly job proves the data left the building; the restore drill proves it can come back. Only the second one is what you are actually buying a backup for.
- “Backup succeeded” answers: were bytes written? Useful, necessary, and not sufficient.
- “Restore completed, verified, in N minutes” answers: can we get the service back, with the data intact, within a time we can live with? That is the promise that matters, and it can only be made by actually doing it.
- A restore that has been run end to end, on a real target, with the elapsed time written down, is worth more than any volume of documentation describing one.
3. What a Real Restore Drill Checks
A drill is not reading the backup file's size. It is standing the system back up from nothing but the backup and confirming it works.
- Restore to a clean target. A fresh host or container, not the machine that still has the original data on it — otherwise you are testing the original, not the backup.
- Measure the time it takes. That number is your real recovery time (RTO). Discovering during an outage that a restore takes nine hours is the kind of surprise a drill exists to prevent.
- Check how much data you would lose. The gap between the last good backup and the moment of failure is your real recovery point (RPO). A nightly backup means up to a day of data gone — fine for some systems, unacceptable for others, and a decision to make on purpose.
- Verify the data, not just the boot. The service coming up is necessary but not enough: spot-check that the records are present, complete, and consistent, not truncated or silently empty.
- Prove you can do it without the person who set it up. A restore only one engineer can perform is a restore that will not happen the week they are on holiday. The runbook should be followable by someone else.
4. How Restores Actually Fail
Drills fail for mundane, recurring reasons — which is the point of running them somewhere other than a live incident:
- The backup excluded something nobody noticed — a table, a config directory, an environment file the application cannot start without.
- The restore depends on a tool, version, or key that is itself only on the machine that was lost.
- The encrypted backup cannot be decrypted because the key was never stored anywhere the restore can reach.
- The restore “works” but takes far longer than anyone assumed, blowing the recovery-time expectation the business was quietly relying on.
- The off-site copy turns out to have stopped updating months ago, and the only current copy was on the hardware that failed.
5. Make It a Routine, Not an Event
A restore tested once, a year ago, describes a system that no longer exists. The data grew, the schema changed, a new service was added — so the drill has to recur.
- Schedule it like any other maintenance, on an interval matched to how fast the system changes and how much a loss would cost.
- Automate what you can so a drill is cheap enough to run often — a scripted restore to a throwaway target that verifies and reports.
- Re-drill after significant change: a migration, a new datastore, a change to what is included. Each one can quietly break the restore the old drill validated.
- Record each drill's result and elapsed time, so the recovery-time number you quote is measured history, not an estimate.
Where This Fits
This discipline underpins both backup and recovery and disaster recovery planning — the latter is simply this idea applied to a whole environment rather than one dataset, with a failover that has itself been rehearsed on a real target and timed. Both fail silently, and both fail at the worst moment, which is why neither is left to documentation alone.
How We Approach It
- Treat the restore, not the backup, as the deliverable — the job succeeding is a precondition, not the goal.
- Restore to a clean target from nothing but the backup, so the test is of the backup and not the original.
- Measure recovery time and recovery point, and write both down as real numbers the business can plan around.
- Verify the data is complete and consistent, not merely that the service starts.
- Make the runbook followable by someone else, and prove it by having them run the drill.
- Re-run on a schedule and after every significant change, keeping a dated log of results.
What You Get
- A restore that has actually been performed, not just configured.
- A measured recovery time and recovery point, instead of an assumption.
- The silent failures — the excluded table, the missing key, the stale off-site copy — found during a drill rather than during a disaster.
- A runbook anyone on the team can follow, kept honest by regular drills.
The question worth asking of any backup you rely on: when was it last restored, how long did it take, and who, other than the person who built it, has done it?