Resource Monitoring
Back to Server Setup · Service and Uptime Checks · Capacity Trending · Monitoring Solutions
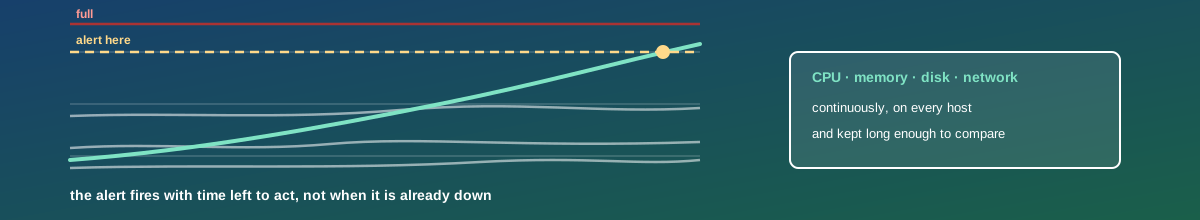
CPU, memory, disk usage and network throughput tracked continuously, with alerts before thresholds turn into outages. This is the layer that watches the machine. Watching whether the application works is a separate job, covered under service and uptime checks — and a server can be perfectly healthy on every metric here while the service is down.
1. What to Collect, and What It Actually Tells You
- CPU — and specifically load and run-queue depth alongside utilisation, because a machine at 100% with nothing waiting is working efficiently, while one at 70% with a growing queue is already slow. Add I/O wait, which looks like a CPU problem and is a disk problem. On virtual machines, watch steal time — time your machine was ready to run and the host gave the processor to someone else.
- Memory — the figure that matters is available, not “free”. A healthy Linux server shows almost no free memory because the kernel is using it for cache, and alerting on free memory produces a permanent false alarm. Watch swap activity as well, which is the early warning.
- Disk — space, and also inodes, which can be exhausted while space remains and produce a baffling “disk full” on an apparently empty filesystem. Then latency and queue depth: a disk at 100% utilisation is the most common invisible bottleneck.
- Network — throughput, but also errors, drops and retransmits. Bandwidth graphs look fine while a faulty cable quietly ruins performance.
2. Set Thresholds That Leave Time to Act
An alert at 95% disk is not an alert, it is a notification of an imminent outage. The threshold should be wherever leaves enough time to do something, which depends on how fast the resource moves and how long the fix takes.
- Disk — alert at a level that gives days, not minutes. On a filesystem growing slowly, 80% is ample; on one that can fill in an hour, 80% is already too late. Better still, alert on time to full rather than on a percentage — see capacity trending.
- Sustained, not instantaneous. Alert on a condition holding for several minutes. A momentary spike is normal and paging someone for it teaches them to ignore alerts.
- Different thresholds for different machines. A batch host is supposed to run at 100%; a web server at 100% is in trouble. One global rule produces noise on one and silence on the other.
3. Alerts Nobody Reads Are Worse Than None
The most common failure of monitoring is not absence but volume. Once alerts are routinely ignored, the one that mattered is ignored too — and everyone believes they are monitored.
- Every alert needs an action. If the response is “nothing, that's normal,” delete the alert or fix the threshold. There is no third option.
- Separate what wakes someone from what waits. Page for what is breaking now; put the rest in a daily digest.
- Suppress the cascade. One failed host should produce one alert, not forty from everything that depends on it.
- Watch the monitoring. A monitoring system that has quietly stopped collecting is indistinguishable from everything being fine. It needs its own check.
4. Keep Enough History to Answer Questions
Metrics kept for a week answer “what is happening now”. Metrics kept for a year answer the more valuable questions: is this slower than last month, what did the last incident look like, when will we run out. Keep full resolution for the recent period and downsample older data — a year of hourly averages costs very little and is what makes trending possible at all.
5. Put It Somewhere People Look
A dashboard per audience, not one dashboard with everything on it. One overview showing whether things are healthy, and a detailed view per service for when they are not. The test is whether someone unfamiliar can tell, in ten seconds, if anything is wrong — if not, it is a data display rather than a dashboard.
What You Get
- Agents collecting the metrics above on every host, with collection itself monitored.
- Thresholds set per machine role, tuned to leave time to act, and alerting on sustained conditions.
- Routing that distinguishes wake-someone from read-tomorrow, with cascade suppression.
- Retention long enough to compare against last month and to support trending.
- Dashboards you can read at a glance, and a documented action for every alert that exists.