Service and Uptime Checks
Back to Server Setup · Resource Monitoring · Certificate Expiry Checker · HTTP Status Reference
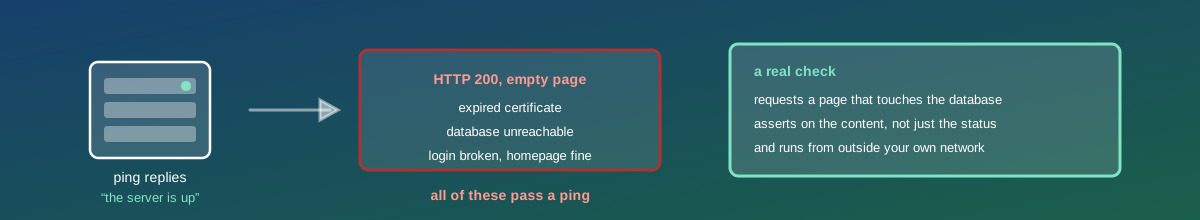
Automated checks confirming the actual application is responding correctly, not just that the server is powered on. The distinction is the entire point of this page. Every one of these passes a ping: an expired certificate, a database the application cannot reach, a deployment that returned an empty page, a login form that stopped working while the homepage is fine. “The server is up” and “the service works” are different claims, and only customers notice the second one failing.
1. Check What the User Does
A check should exercise the path a real request takes, not the shallowest thing that returns a response.
- Assert on content, not only on status. A 200 response proves a web server answered. Check that an expected string is present — that is what catches the empty page after a bad deployment.
- Go through the whole stack. Request a page that genuinely reads the database, so the check fails when the database is unreachable. A static page served by the proxy proves nothing about the application behind it.
- Check the important journeys, not just the homepage. Logging in, searching, adding to a basket, submitting a form. These break independently, and the homepage is usually the last thing to notice.
- Include the write path where you safely can. A read-only check passes happily while a full disk or a read-only database has made the system useless for anything that matters.
- Record response time, not just success. A service answering in eight seconds is failing in every sense that matters to a user, and a pass/fail check calls it up.
2. Check From Outside
A check that runs on the same server, or inside the same network, cannot see the problems your users see: DNS resolving wrongly from outside, a firewall rule blocking a region, an expired certificate that internal clients happen to trust, a CDN misconfiguration, the whole data centre being unreachable. Run checks from at least one external vantage point — and where the audience is geographically spread, from more than one, because a route being broken from one country is a real and hard-to-spot failure.
Internal checks still have their place: they distinguish “the application is broken” from “the path to it is broken”, which is the first question in any incident. Run both.
3. Health Endpoints Worth Having
A dedicated health endpoint is useful if it is honest. It should verify the dependencies the service actually needs — database reachable, cache reachable, disk writable — and report degraded rather than simply up or down where the service can run without an optional piece. It should be cheap enough to poll frequently, and it should not require authentication while also not disclosing internal detail to the public.
The anti-pattern is an endpoint that returns “OK” unconditionally. It exists, something polls it, everyone believes the service is monitored, and it has never once failed.
4. The Checks People Forget
- Certificate expiry, alerting weeks ahead rather than on the day — a self-inflicted outage that is entirely preventable. Our certificate expiry checker covers the ad-hoc case.
- Domain expiry, which is rarer and far worse.
- Scheduled jobs. A nightly job that stops running fails silently by definition. Have the job report that it finished, and alert when the report does not arrive.
- Backups completing — and, separately, restores being tested. See backup and recovery.
- Queue depth. A consumer that has died leaves a service that accepts work and never does it, which passes every other check.
- Third-party dependencies, so that when a payment provider is down you know before your customers tell you.
5. Tune the Alerting
Require several consecutive failures, from more than one location, before declaring an outage — a single missed check is usually the checker's network, not yours. Set the interval by how quickly you need to know: a minute for a critical service, five for the rest. And define what “up” means before you publish an availability figure, because uptime measured by pinging a server and uptime measured by completing a purchase are very different numbers.
What You Get
- End-to-end checks on the journeys that matter, asserting on content and recording response time.
- External vantage points as well as internal ones, so failures are distinguishable.
- Honest health endpoints that verify real dependencies.
- Certificate, domain, scheduled-job, backup and queue checks configured.
- Alerting tuned against false positives, and an availability definition you can stand behind.