Responsive Support
Back to Server Setup · Escalation Path · Incident Handling · Service Offerings
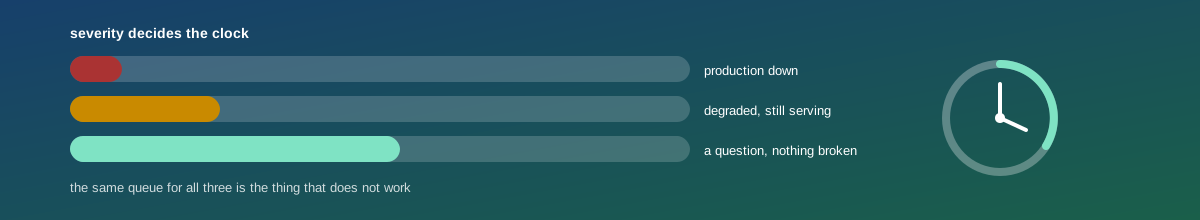
Defined response times based on severity, so a down production service and a minor config question aren't handled on the same timeline. A single queue fails both: the urgent thing waits behind the trivial one, and the trivial one gets an urgency it never needed.
1. Severity Is About Impact, Not Feelings
Severity has to be decidable by whoever is looking at it, at three in the morning, without a discussion. That means defining it by observable impact:
| Level | What it means | Typical shape of the response |
|---|---|---|
| Critical | Production down or unusable, or data at risk. Nobody can work. | Minutes, any hour, until it is resolved. |
| High | Degraded but serving, or one important function broken. There is a workaround. | Within the hour, during agreed hours. |
| Normal | Something is wrong, nothing is stopped. A request or a change. | Same or next working day. |
| Low | A question, an improvement, something to look at when there is time. | Scheduled, not queued indefinitely. |
Two rules keep this honest. You can always raise the severity — if something is more serious than it first appeared, it moves up without an argument. And everything cannot be critical; where it is, the levels stop meaning anything and the genuinely critical thing loses its priority.
2. Respond and Resolve Are Different Promises
A response time is a commitment that a person has taken it on and started, and it is a promise that can be kept. A resolution time is not, because how long a fix takes depends on what is broken — and a provider who guarantees one either pads it enormously or will break it.
What can be committed alongside the response: a first assessment within a stated period, and updates at a stated interval while work continues. In practice the update cadence matters as much as the initial response, because silence during an outage is what makes it feel unmanaged even when it is being worked on properly.
3. Say What the Hours Actually Are
“24/7 support” means very different things, and the difference should be written down rather than discovered:
- Business hours — and which timezone, and which public holidays.
- Extended or on-call — someone reachable outside hours for critical issues, with a realistic expectation of how quickly a person who was asleep can be at a keyboard.
- Genuine round-the-clock — which requires a rota of several people and is priced accordingly. An arrangement where one person is nominally always available is not 24/7; it is one person who will eventually be unavailable.
We would rather commit to hours we can keep than advertise cover we cannot. If out-of-hours critical response is needed, that is a specific arrangement with a specific cost, not a bullet point.
4. How to Reach Us, and What to Say
Critical issues need a channel that reaches a person — phone or a paging route — not an email address. Lower severities go to the normal channel. The escalation path covers who and how.
What makes a report actionable, and worth putting in a template: what you were doing, what happened, when it started, whether anything changed recently, and whether it affects everyone or one person. “The site is down” starts a diagnosis; “checkout has returned an error for all users since about 14:20, we deployed at 14:15” nearly finishes one.
5. Measure It, and Publish the Measurement
Response commitments only mean something if they are tracked. We record time to first response and time to resolution per severity, and report against them — including when we miss. A provider who reports only the months they did well is not reporting.
What You Get
- Severity definitions written in terms of impact, so classification is not a negotiation.
- A response commitment per severity, with an update cadence during ongoing work.
- Explicit hours of cover, including out-of-hours arrangements where they exist.
- Contact routes per severity, and a reporting template that makes diagnosis faster.
- Measured performance against the commitments, reported honestly.