Direct Incident Handling
Back to Server Setup · Responsive Support · Root Cause Diagnosis · Post-Incident Follow-Up
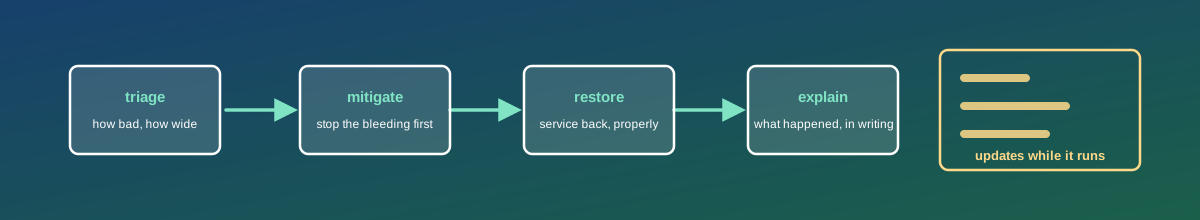
We work the problem ourselves — triage, mitigate, restore — with status updates as we go. Not a ticket routed to a queue, not a list of things for you to try, and not a request that you gather diagnostics first. The person who answers is the person who fixes it.
1. Triage: How Bad, How Wide, How Fast
The first few minutes are about scope, not cause. Three questions, answered before anything is changed:
- What is the actual impact? Everyone or one user, all functions or one, completely down or slow. This sets the severity and therefore everything that follows.
- Is it getting worse? A stable failure and a spreading one deserve different responses, and a spreading one may justify a drastic mitigation that a stable one does not.
- Is data at risk? This changes the order of operations entirely. Where data could be lost or corrupted, stopping writes comes before restoring service — a service that is down for another hour is recoverable, and corrupted data may not be.
2. Mitigate: Stop the Bleeding
Mitigation is not the fix. It is whatever restores service fastest while the real cause is still unknown, and choosing it over a proper fix is deliberate rather than lazy. The common moves:
- Roll back the recent change. If it started after a deployment, reverting is almost always faster than diagnosing, and it can be undone.
- Take the failing component out. Remove a bad node from the pool, fail over to the standby, disable the feature that is breaking.
- Shed load. Rate-limit, disable an expensive endpoint, put up a maintenance page for part of the service. A partially working system beats a completely overwhelmed one.
- Buy room. Clear disk space, restart the leaking process, add capacity. Explicitly temporary, and recorded as such so it is not mistaken for a resolution.
Every mitigation gets written down as it is applied, because temporary measures that nobody recorded become permanent by accident — and a rate limit left on for six months is its own incident later.
3. Restore: Properly, and Verified
Service restored means verified working, not “the error stopped appearing”. That means checking the actual user journey rather than the health endpoint, confirming the monitoring agrees, and looking for the second-order damage: the queue that built up while the system was down, the jobs that did not run, the retries still arriving, the data written in a degraded state. Coming back under the full weight of a backlog is a common way to fail twice, so restoration is staged where the backlog is large.
And we note explicitly which mitigations are still in place, so removing them is a task rather than an oversight.
4. Communicate While It Runs
This is the part most often done badly, and it is the part you experience. Silence during an outage is indistinguishable from nothing being done.
- Acknowledge immediately — that we have it, and what we know so far.
- Update on a cadence, even when the update is “still investigating, nothing ruled in yet”. A promised interval kept is worth more than an occasional detailed message.
- Separate fact from hypothesis. “We believe it is the database” and “we have confirmed it is the database” are different, and conflating them misleads people making decisions on the other side.
- Give an honest estimate, or say you cannot. “We do not yet know how long” is acceptable. An optimistic estimate repeatedly missed is not.
- Say who is doing what, and who the contact is — see the escalation path.
- Close the loop explicitly. A clear statement that it is resolved, what was done, and what happens next.
5. Who Does What
For anything sustained, one person holds the incident — makes decisions, keeps the timeline, handles communication — and the others work the problem. This sounds like overhead on a small team and is not: the failure mode without it is two people making conflicting changes at once, or everyone investigating and nobody telling you anything.
Everything done is logged as it happens, with timestamps. That record is what makes the diagnosis and the follow-up possible, and it cannot be reconstructed afterwards from memory.
What You Get
- Triage on impact, spread and data risk before anything is changed.
- Mitigation chosen for speed, applied deliberately and recorded as temporary.
- Restoration verified on the real user journey, with the backlog and second-order effects handled.
- Acknowledgement immediately and updates on a kept cadence, with fact separated from hypothesis.
- A timestamped action log, which becomes the input to diagnosis and follow-up.