Escalation Path
Back to Server Setup · Responsive Support · Incident Handling · Disaster Recovery
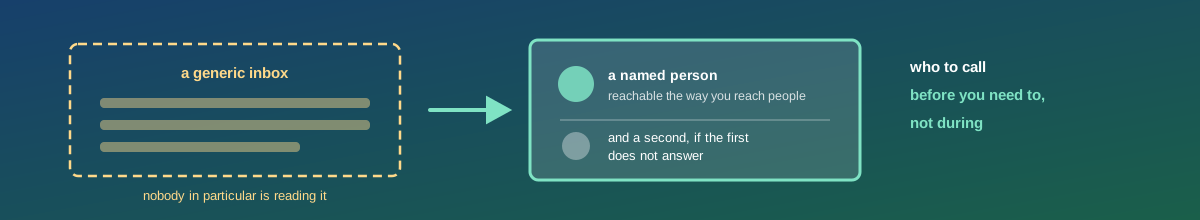
A clear point of contact for urgent issues, instead of a generic support inbox. The problem with a shared address is not that it is impersonal. It is that nobody in particular is responsible for reading it, so at 2am on a Sunday it is read by nobody at all — while the sender reasonably assumes it has been received.
1. A Named Person, Reachable the Way People Are Reachable
For anything urgent: a name, a phone number, and a route that produces a notification on a device someone will hear. Email is not that route. The details are agreed at handover and kept current, because a contact list that has gone stale is worse than none — it produces confident attempts to reach someone who left.
Alongside it, a documented second contact for when the first does not answer, with a stated wait before moving on. “If no response in fifteen minutes, call the second number” removes the most wasteful part of an out-of-hours incident, which is the caller not knowing whether to keep waiting.
2. Match the Route to the Severity
The point of having a phone route is that it is reserved. If it is used for routine questions it stops being answered urgently, and then it is a phone number that behaves like an inbox. So: critical issues by phone or paging, everything else through the normal channel. The severity definitions say which is which, and using the wrong route is worth correcting gently rather than ignoring, because the reservation is the whole value.
3. The Escalations That Are Not Ours
An escalation path that stops at us is incomplete, because plenty of incidents are resolved by someone else. Arranged in advance, and documented:
- Hosting or cloud provider — account number, support tier, how to raise a priority case and who is authorised to. Discovering at 3am that your support plan does not include phone access is a specific and avoidable kind of bad night.
- Software vendors under support contract, with the contract reference to hand.
- Connectivity and domain providers — and note that a DNS or registrar problem may be what is stopping you reaching your own systems, so those credentials need to be accessible independently.
- Your own people — who decides to declare a disaster, who can authorise a change that affects customers, who speaks to customers. Decisions we are not entitled to make need a person attached before we need them, not during.
4. Make It Work When Things Are Broken
An escalation path that lives only in the system that is down is not a path. The contact list, the account references and the runbooks need to be reachable from a phone, from outside the network, when the wiki is unavailable. A printed copy sounds old-fashioned and has saved more incidents than most tooling.
The same applies to credentials for the escalation itself — provider portal access, the out-of-band console, the DNS registrar. If those are behind the infrastructure that is down, the path does not exist. This is the same reasoning that shapes disaster recovery planning.
5. Test It Occasionally
Escalation paths decay silently: people change roles, numbers change, a support contract lapses, a portal login stops working. Verifying the chain periodically — a call that goes through, a test case raised with a provider, a check that the credentials still work — takes half an hour and is the difference between having a path and having a document about one.
What You Get
- Named contacts with real phone numbers, a stated second contact, and a defined wait before escalating.
- Routes matched to severity, with the urgent route kept for urgent things.
- Third-party escalation details prepared in advance, including support tiers and who may raise a case.
- Your own decision-makers named for the calls we cannot make.
- All of it available offline and off-network, and verified on a schedule.