Before-and-After Measurement
Back to Performance Tuning and Capacity Planning · Kernel and Filesystem Parameters · Connection Pool Sizing · Caching Strategy · Service Offerings
Every tuning change verified against real metrics, so you know what actually helped versus what just felt like it should. This is what separates tuning from rearranging, and it is skipped more often than any other step because the change already seems obviously correct.
It is the same discipline as evidence before action, applied at the other end. That page is about choosing what to change; this one is about proving the change did something.
1. A Single Number Cannot Tell You
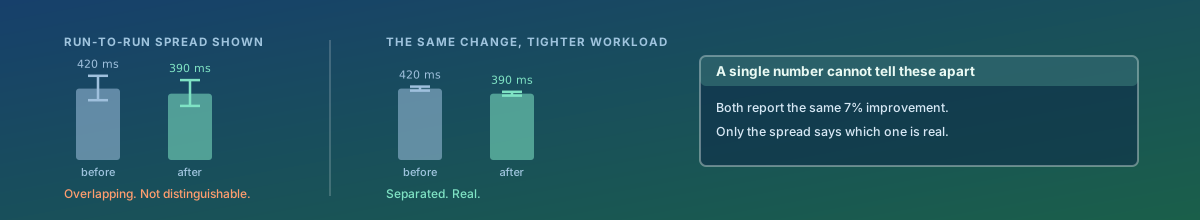
Run the same unchanged system twice and the numbers differ. Different cache state, a different neighbour on the host, a background job, a different data distribution in the sample. That run-to-run spread is the floor below which no measurement can distinguish anything.
The illustration above is one change measured two ways. Both report a 7 per cent improvement. In the first the spread of each run overlaps the other entirely, so the figure is indistinguishable from having changed nothing. In the second the ranges are separate and the same 7 per cent is real.
The practical rule: measure the unchanged system twice before measuring the change. The difference between those two runs is your noise floor, and any result smaller than it is not a result.
2. Measure the Same Way, or Do Not Compare
- Same data volume. A query measured against last month's table is not comparable to one measured against today's.
- Same cache state. The second run of anything is faster. Either warm both or clear both, and say which you did.
- Same concurrency. A change that helps a single request can hurt under load, which is exactly when it matters.
- Same time of day, where the system shares anything with anyone.
- Same metric. Comparing a mean to a 95th percentile is the easiest way to produce an improvement that does not exist.
3. Percentiles, Because the Mean Hides the Complaint
A mean response time improving from 240 ms to 210 is consistent with the slowest requests getting slower, if the fast ones got faster enough to compensate. Users do not experience the mean; the ones who complain are experiencing the tail.
- Record p50, p95 and p99 on both sides. A change that moves the median and worsens p99 is usually a loss, whatever the average says.
- Record the maximum too. It is noisy and it is where timeouts live.
- Count errors as part of the result. A configuration that is faster and fails one request in a thousand has not improved anything.
4. Look for What Got Worse
Most tuning moves a cost rather than removing it, and the measurement usually covers only the side expected to improve.
- An index speeds reads and slows every write to that table.
- A cache improves latency and adds memory, invalidation and a new failure mode.
- A larger pool helps the application and loads the database — see connection pool sizing.
- Relaxed durability settings buy speed with a risk that only appears during a crash.
So the after-measurement has to include the side you were not trying to change. A tuning change with no observed downside has usually not been measured widely enough.
5. Write the Prediction Down First
Before the change: what should improve, by roughly how much, and what might get worse. It takes a minute and does two things.
It makes the result falsifiable — an improvement of 2 per cent where 30 was expected means the mechanism is not understood, even though the number moved in the right direction. And it protects against the version of success where the figure is read afterwards and a story is built to fit it.
6. Remove What Did Not Help
The step that almost never happens. A change that showed no measurable improvement should be reverted, not kept because it seems sensible or because it took effort.
Kept changes accumulate. Each is a setting nobody can justify, a layer nobody can safely remove, and a complication in the next investigation. Years later a machine carries a dozen tuning changes of which perhaps three ever did anything, and nobody knows which three.
Where a change stays, record three things with it: the measurement before, the measurement after, and the date. That record is what lets someone remove it later with confidence.
How We Approach It
- Establish the noise floor by measuring the unchanged system twice, so there is a threshold below which nothing counts.
- Record the baseline: percentiles, errors, and the resources on both sides of the change.
- Write the prediction, including what might get worse.
- Change one thing, and measure identically.
- Compare against the noise floor, not against zero, and check the side that was not meant to change.
- Keep it with its evidence, or revert it, and record which and why.
What You Get
- A noise floor for your environment, so small results can be recognised as nothing.
- Before-and-after figures at p50, p95 and p99 with error counts, not a single average.
- A stated prediction per change and a note wherever the result disagreed with it.
- The cost side measured as well as the benefit side, so a moved cost is not mistaken for a removed one.
- Changes that did nothing reverted, and the ones that stayed documented with the numbers that justify them.
The question this makes answerable, which is surprisingly hard to answer on most systems: of the tuning changes currently in place, which ones can you show helped?