Kernel and Filesystem Parameters
Back to Performance Tuning and Capacity Planning · Connection Pool Sizing · Caching Strategy · Before-and-After Measurement · Service Offerings
File descriptor limits, TCP settings, and I/O schedulers adjusted for actual workload instead of distro defaults sized for a generic server. The defaults are not wrong; they are a compromise for a machine whose job nobody knew. Yours has a job.
This is the parameter-level companion to performance tuning at build time, which covers the method and the wider picture. Here the subject is the specific settings, which default bites which workload, and how to know before it does.
1. The Defaults That Become Walls
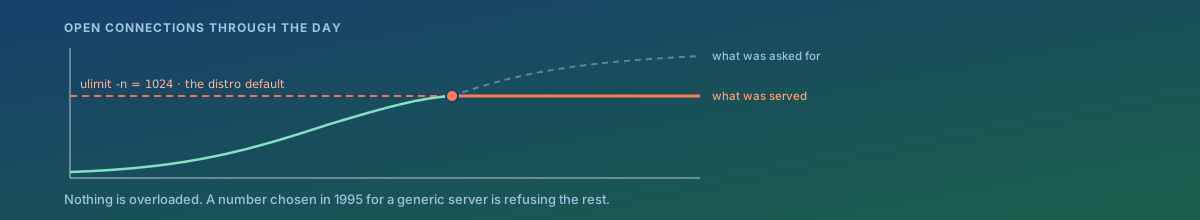
What makes these dangerous is that the machine looks healthy while they bite. CPU is low, memory is fine, the disk is idle — and connections are being refused, as in the illustration above. There is no gradual degradation to notice.
| Limit | What happens when you reach it | Who hits it |
|---|---|---|
| Open file descriptors | Accepts fail, log writes fail, the application reports errors that read as bugs | Anything holding many concurrent connections — a proxy, a websocket server, a busy database client |
Listen backlog (somaxconn) |
Connections dropped during bursts, seen by the client as a timeout rather than a refusal | Services with spiky arrival patterns |
| Ephemeral port range | Outbound connections fail once the range is exhausted by sockets in TIME_WAIT | A service making many short-lived outbound calls to one destination |
| Connection tracking table | Packets silently dropped once full, with a kernel log line nobody is watching | Any host with a stateful firewall and high connection rates |
| Inotify watches | File watchers stop working, usually in a build tool, usually blamed on the tool | Development machines and CI runners |
2. The File Descriptor Limit Is Three Limits
Raising it is the most common tuning task and the most commonly done incompletely, because there are several in series and the smallest wins.
- The kernel maximum — a system-wide ceiling, usually generous already.
- The per-process soft and hard limits, which a shell shows and which a login session inherits.
- The limit the service actually runs with, which under systemd comes from
the unit file and ignores whatever the shell or
limits.confsays.
That last one is the trap. Raising the limit in a configuration file, confirming it in a terminal, and restarting the service changes nothing, because the service was never started from that terminal. Check the running process rather than the shell.
3. Match the I/O Scheduler to the Device
Schedulers exist to reorder requests so a mechanical head travels less. On a device with no head, that work is pure overhead.
- NVMe and SSD — none, or a minimal scheduler. The device reorders internally and does it better.
- Rotational disks — a scheduler that merges and orders is worth real time, because a seek costs milliseconds.
- Virtual disks and SANs — the guest has no idea what the storage actually is, and guessing wrong is common. Measure latency under load rather than reasoning about the hardware.
- Read-ahead matters as much as the scheduler and is easier to get wrong: large read-ahead helps sequential work and wastes bandwidth on random work.
4. Filesystem Settings Worth Checking
- Access-time updates. Recording a read as a write is pointless for most
workloads;
relatimeis the usual default andnoatimeis often correct. - Journal mode and barriers. Relaxing them is a genuine speed-up and a genuine durability trade. Make it deliberately, or not at all.
- Reserved blocks. Five per cent of a large data volume held back for root is a lot of space on a disk that is not a root filesystem.
- Inode exhaustion — a disk reporting free space while refusing to create files. Monitor inodes as well as bytes; the error message does not say which ran out.
5. TCP Settings, and the Ones to Leave Alone
Network tuning attracts copied configuration more than any other area, and most of it is a decade out of date. Modern kernels ship sensible values, and several once-popular settings are now harmful or removed.
- Worth setting deliberately: the listen backlog, the ephemeral port range where outbound volume is high, socket buffer maxima on genuinely high-bandwidth links, and keepalive timings where idle connections pass through a NAT that drops them.
- Worth leaving alone: congestion control defaults, most buffer autotuning, and anything recommended by a post that does not say which kernel version it applied to.
- Worth measuring first: retransmit rates and socket queue overflows. If neither is happening, TCP is not your problem and tuning it will not help. See resource utilization breakdown.
6. A Setting That Does Not Survive a Reboot Is Not a Fix
A value applied at the command line disappears, and it disappears months later, during a restart nobody connected to the symptom. The change belongs in configuration, with three things alongside it: what it was, why it was changed, and what measurement justified it.
Where the machine is built by automation, the parameter belongs there rather than on the machine — see infrastructure as code. The failure mode otherwise is a host that was tuned, rebuilt, and quietly went back to defaults.
How We Approach It
- Read the current effective values from the running processes, not from the files that are supposed to set them.
- Compare against the workload: peak concurrent connections against the descriptor limit, outbound connection rate against the port range, connection rate against the tracking table.
- Check the storage settings against the actual device, measured rather than assumed, which matters most on virtualised disks.
- Change what the measurements justify, one at a time, and leave the rest alone.
- Persist every change in configuration or in the build, with the reason recorded next to it.
- Add alerting on the limits themselves, so the next one announces itself instead of arriving as a refused connection.
What You Get
- The effective limits as the running services actually see them, which frequently differ from what the configuration says.
- Headroom against each limit at observed peak, so you know which one you will reach first.
- Storage and network settings matched to the real device and the real traffic, with the copied-in values that no longer apply removed.
- Every change persisted and annotated with its reason and its measurement.
- Alerting on approach to each limit, so the next wall is visible before you hit it.
The symptom to recognise: a machine with plenty of everything, refusing work. That is almost never capacity. It is a number someone chose for a different server.