Caching Strategy
Back to Performance Tuning and Capacity Planning · Kernel and Filesystem Parameters · Connection Pool Sizing · Before-and-After Measurement · Service Offerings
Application, query, and CDN caching applied where it actually reduces load, not layered on everywhere by default. The default assumption is that a cache can only help, and it is wrong in a specific and measurable way.
1. A Cache That Misses Is Not Free
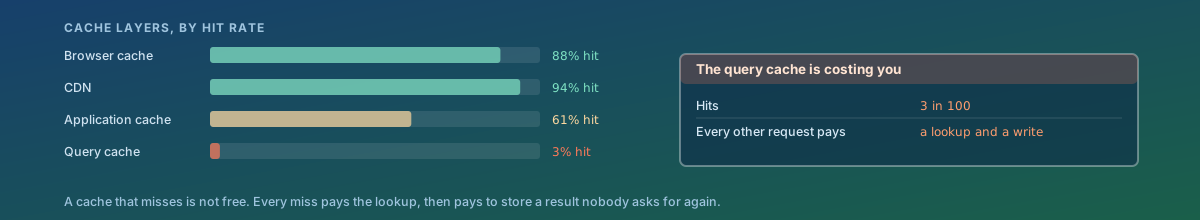
Every miss costs twice: the lookup that found nothing, and the write that stores a result nobody will ask for again. At a 3 per cent hit rate — the bottom row of the illustration above — ninety-seven requests in a hundred pay both and gain nothing.
So the question for each layer is not “could this be cached” but “how often is the same thing asked for twice”. Where the answer is rarely, the cache is a tax. Measure the hit rate of what you already have before adding another layer, because a layer with a low rate is usually easier to remove than to improve.
2. The Layer Closest to the User Is Worth the Most
The same hit avoids more work the further out it happens. A CDN hit skips your network, your server, your application and your database; a query cache hit skips only the query.
| Layer | What a hit avoids | What makes it hard |
|---|---|---|
| Browser | The request entirely | You cannot clear it; a wrong long expiry is wrong for months |
| CDN | Everything from your network inwards | Anything personalised fragments it into uselessness |
| Application | The computation and the queries behind it | Knowing when the answer stopped being true |
| Query | One query | Low hit rates, because exact repeats are rarer than they seem |
Effort therefore belongs at the top of that table, and the common mistake is the reverse: the query cache is the easiest to switch on and the least valuable when it works.
3. Invalidation, Which Is the Actual Work
Storing is trivial. Knowing when a stored answer stopped being true is the engineering, and it is why a cache is a permanent obligation rather than a one-off change.
- Expiry by time is simple, always a little wrong, and usually right enough. The question it asks is how stale you can afford to be — and for most data the honest answer is far more than people assume.
- Invalidation by event is correct and fragile: every write path must know every cache that holds the thing it changed, forever, including the ones added later.
- Keying is where the bugs are. A key that omits something the answer depends on — the user, the locale, the permissions — serves one reader's data to another. This is the cache bug that becomes a security incident.
4. The Stampede
A popular entry expires, and every request that wanted it arrives at the database at once. The cache was absorbing a hundred requests a second; now all hundred land together, on a system sized for the cached load.
- Let the first request recompute while the rest serve the stale value. The most effective single measure, and it costs a little staleness.
- Lock the recomputation, so one worker rebuilds while the others wait for it rather than duplicating the work.
- Jitter the expiry times, or everything populated together expires together, which is how a restart becomes an outage twenty minutes later.
5. What Not to Cache
- Anything cheap. If the underlying operation costs less than the cache round trip, you have added latency.
- Anything unique per request. It will never be hit, and section 1 applies.
- Anything whose staleness is unacceptable — a balance, a permission, a stock level — unless the invalidation is genuinely reliable.
- A slow query you have not looked at. Caching is sometimes the right answer and is often a way of not fixing a missing index. See slow query identification first.
That last one is worth dwelling on. A cache over a bad query hides it: the query stays bad, the first request after every expiry still waits, and the problem reappears the moment the hit rate drops.
6. Measure the Layer, Not the Idea
Every cache should report hit rate, miss cost and eviction rate, and those three numbers decide whether it stays.
- A low hit rate means remove it or fix the key.
- A high eviction rate means it is too small to hold the working set, and is thrashing — filling and emptying without ever serving.
- A hit rate that drifts down over months is a cache whose assumptions have expired, which happens quietly and is never noticed without the metric.
- The before-and-after is the only thing that settles whether a layer earned its place — see before-and-after measurement.
How We Approach It
- Measure what the existing layers achieve — hit rate, eviction rate, and what a miss actually costs.
- Find the repeats. Caching only pays where the same answer is wanted more than once, and the request log says where that is.
- Work from the outside in, since a hit further out avoids more.
- Decide invalidation before adding anything, including what the key must contain to keep one user's data away from another.
- Protect against the stampede with stale-while-revalidate, a recomputation lock, and jittered expiry.
- Remove the layers that do not earn their keep, which is the part that normally never happens.
What You Get
- Hit rate, eviction rate and miss cost for every existing layer, and a recommendation to keep, fix or remove each.
- Caching placed where repeats actually occur, worked from the outermost layer inwards.
- An invalidation approach written down per cache, with the key contents justified.
- Stampede protection on anything popular enough to need it.
- Monitoring on each layer, so a cache that stops earning its place says so.
The uncomfortable question worth asking of any existing cache: what is its hit rate? If nobody knows, it is as likely to be costing you as saving you.