Controlled Environment
Back to Performance Tuning and Capacity Planning · Realistic Traffic Modeling · Breaking Point Identification · Pre-Launch Validation · Service Offerings
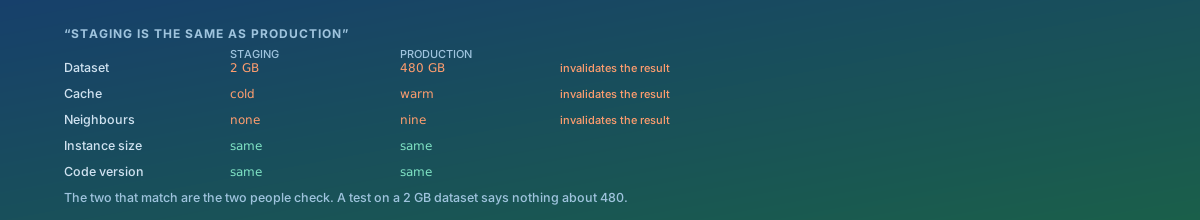
Tests run against staging or an isolated environment, so finding the breaking point doesn't create an outage of its own. Which raises the question the illustration above is about: whether the result from that environment means anything.
1. “The Same as Production” Usually Is Not
Parity is checked on the things that are easy to check — instance type, code version, configuration — and those are rarely what decides a performance result. The three that do are the three that differ.
| Difference | Why it invalidates the result |
|---|---|
| Dataset size | Queries change plan as tables grow. A test on 2 GB uses an index that the planner abandons at 480, and indexes that fit in memory on staging do not in production |
| Cache state | A warm production cache serves most reads. A cold staging one sends them all to disk, or a tiny staging dataset caches entirely and sends none |
| Shared hardware | Staging alone on a host behaves differently from production competing with nine neighbours for the same disks |
| Data distribution | Evenly generated test rows hide the skew that real data has. The customer with four hundred thousand records is where the slow query lives |
| External dependencies | Mocked services answer instantly. Real ones are slow sometimes, which is when connection pools drain |
2. Dataset Size Is the One to Fix First
If only one difference can be eliminated, make it this one. A production-sized dataset changes query plans, index behaviour, cache ratios and backup windows all at once, and nothing else on the list has that reach.
- A restored copy is best, with personal data masked rather than removed, so volumes and distributions survive.
- Generated data must be skewed deliberately: uniform rows are the easiest thing to generate and the least like reality.
- Where a full copy is impossible, say so in the result. A conclusion from a tenth of the data is a hypothesis about the other nine.
Masked production data brings obligations with it — it is still personal data, it needs the same access controls, and it needs deleting afterwards. See security and compliance needs.
3. When Production Is the Only Honest Option
Sometimes no copy is affordable and the question still needs answering. It can be done, with the blast radius controlled rather than hoped about:
- Off-peak, with people watching, and a stated abort condition agreed beforehand rather than decided under pressure.
- A single instance taken out of the load balancer and loaded on its own, which measures one node's ceiling without risking the service.
- Shadow traffic — real requests duplicated to a test instance whose responses are discarded. Realistic input, no user impact, and it will not test writes.
- An abort that is one command, already tested, and runnable by whoever is watching.
What makes this acceptable is not confidence that nothing will break. It is having decided in advance what you will do when something does.
4. Isolate the Load Generator Too
The generator is part of the experiment and is regularly the thing that saturates first.
- Generate from outside the target's network, or you are measuring a loopback.
- Watch the generator's own CPU and sockets. A result that plateaus because the generator ran out of ports is a measurement of the generator.
- Check it can produce more load than the target can take, before concluding anything about the target's ceiling.
- Keep its clock synchronised with the target's, or the timeline afterwards cannot be read.
5. Say What Was Different
Every result should carry the deltas alongside it — dataset ratio, cache state, dependencies mocked or real, hardware shared or dedicated. Not as a disclaimer, but because it determines how the number should be used.
A ceiling found on a tenth of the data is still useful: it bounds the problem, it finds the failure sequence, and it can be compared against itself after a change. It is just not the production ceiling, and the difference between those two statements is the whole value of recording the deltas.
How We Approach It
- Compare the environments on what matters — data volume and distribution, cache state, hardware sharing, dependencies — rather than on instance type.
- Close the dataset gap first, with a masked restore where possible and deliberately skewed generation where not.
- Decide the blast radius before any test that could affect production, with an abort condition and a tested abort command.
- Verify the load generator can exceed the target, and watch its own resources during the run.
- Record the deltas with every result, so the numbers are used for what they can support.
- Leave the environment reproducible, so the next test compares against this one rather than starting over.
What You Get
- A parity assessment naming the differences that actually affect the result, and what each does to it.
- A realistic dataset, masked or deliberately skewed, with its handling obligations stated.
- An agreed blast radius and a tested abort for anything touching production.
- A load generator confirmed capable of exceeding the target rather than assumed to be.
- Results that carry their own caveats, so a staging ceiling is never quoted as a production one.
The test of a test environment is uncomfortable and short: how big is its database compared to the real one? If the answer is “much smaller”, the ceiling it reports is not yours.