Breaking Point Identification
Back to Performance Tuning and Capacity Planning · Realistic Traffic Modeling · Controlled Environment · Pre-Launch Validation · Service Offerings
Pushing past expected load deliberately, so you know the actual ceiling instead of an assumed one. Most load testing stops at the expected peak and reports a pass. That tells you the system survives what you predicted, and nothing about what happens when you are wrong.
1. Systems Collapse, They Do Not Plateau
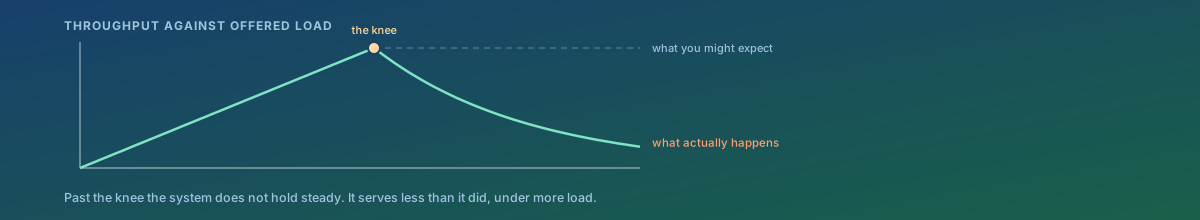
The intuition is that a saturated system serves its maximum and queues the rest. Real systems do worse than that, as the illustration above shows: past the knee, throughput falls, and the system under heavy load serves considerably less than it did at its best.
The mechanisms compound each other:
- Queues consume memory, which takes it from the work.
- Context switching rises as concurrency grows, so less of each second is spent on anything useful.
- Timeouts begin firing, and work already done is thrown away unfinished — the system is now busy producing nothing.
- Clients retry, so failing requests return as additional load. This is the one that turns a slowdown into a collapse.
Which is why the practical ceiling is the knee, not the peak measured anywhere beyond it. Operating near the knee means a small surge pushes you over, and over is much further down than it looks.
2. Find What Fails First, and in What Order
The number is the least valuable output. The failure sequence is the useful one, because it tells you what to fix and what will happen next time.
- Which resource saturated — and it is frequently not the one expected. See resource utilization breakdown.
- What failed second, as a consequence of the first. A saturated database exhausts the connection pool, which stalls the application, which fails the health check, which removes the instance from the load balancer and sends its traffic to the others.
- Whether failure is contained or contagious. The example above is contagious: the remedy makes it worse by concentrating load on the survivors.
- What the user experiences at each stage — slow, then errors, then timeouts, then nothing.
3. Recovery Is the Harder Question
A system that breaks at a known load and recovers in thirty seconds is in decent shape. One that breaks at twice that and then stays broken after the load is removed is not.
- Take the load away and time the recovery. If it does not recover without a restart, that is the finding.
- Watch for the retry storm. Removing the load does not remove the queued retries, and the load after an incident is routinely higher than the load that caused it.
- Check for permanent damage: a lock not released, a corrupted cache, a queue that never drains, a connection leak.
- Look at what did not come back. A background job that died quietly during the test is the kind of thing found weeks later.
4. Degrade Deliberately Instead
If the collapse past the knee is unacceptable — and it usually is — the answer is not more capacity. It is refusing work on purpose, above the knee, so that the system serves what it can rather than failing at everything.
- Rate limiting and admission control. Turning away ten per cent of requests quickly beats serving none of them slowly.
- Queue limits with a short wait. An unbounded queue converts a capacity problem into a memory problem and then into a crash.
- Shed the expensive work first. Disable reports and exports under load and keep the core path alive.
- Make clients back off. Retries with exponential backoff and jitter are the difference between recovery and a self-sustaining storm.
5. Test to Failure, Deliberately and Safely
Finding the real ceiling means going past it, which is why this work belongs in an isolated environment — see controlled environment. The test plan matters:
- Ramp in steps and hold at each, so the knee is identifiable rather than smeared across a continuous ramp.
- Watch the resources throughout, not only the response times, so the cause is captured alongside the effect.
- Keep going past the first failure. The second and third failures are the interesting part.
- Record everything, because the point is to compare against it after changes.
How We Approach It
- Ramp in steps to well beyond the expected peak, holding at each level long enough for queues to settle.
- Identify the knee, which is the practical ceiling, rather than the highest number reached.
- Record the failure sequence — what saturated, what failed because of it, and what the user saw at each stage.
- Remove the load and measure recovery, including whether anything stayed broken.
- Recommend admission control where the collapse is steep, since more capacity moves the cliff without removing it.
- Re-run after changes against the recorded baseline.
What You Get
- The knee, as a number, with the headroom between it and your current peak.
- The failure sequence in order, which is what tells you where to spend.
- Recovery behaviour, including anything that needed a restart.
- A degradation plan where the collapse is steep: what to shed, at what point, and how clients should behave.
- A repeatable test and a recorded baseline, so the ceiling can be re-measured after any change.
The question most capacity plans cannot answer: not what happens at your expected peak, but what happens at twice it — and whether you come back on your own.