Pre-Launch Validation
Back to Performance Tuning and Capacity Planning · Realistic Traffic Modeling · Breaking Point Identification · Controlled Environment · Service Offerings
A scheduled load test ahead of any known traffic event, not a hope that current capacity will happen to be enough. The date is almost always known well in advance. What is missing is a step in the plan that uses it.
1. Weeks Before, Not Days
A test two days before a launch can only produce two outcomes: everything is fine, or a crisis. There is no time to act on anything in between, which is most of what a test finds.
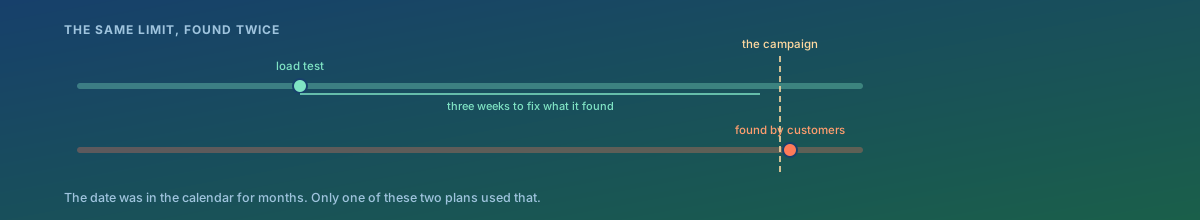
Work backwards instead, as the illustration above does. The test belongs far enough ahead that its findings can be fixed, re-tested and deployed through a normal release process.
- Three weeks is a reasonable default for anything with a code fix in it.
- Longer where the remedy might be capacity, since provisioning has its own lead time — see lead-time awareness.
- Leave room for a second run. The first test finds a limit, the fix moves it, and the second finds the next one. There is always a next one.
2. What Should Trigger One
Launches are the obvious case and the minority. The useful list is wider and is already known to someone:
- A marketing campaign, particularly an email or push send, where the whole audience arrives within an hour.
- Onboarding a large client, where the initial data import is usually the biggest load that account will ever produce.
- A seasonal peak that recurs annually — and recurs larger each year, while the testing often does not.
- An infrastructure change: a migration, a database upgrade, a new region. Capacity after the change is a different question from capacity before it.
- A press appearance or a partner announcement, which arrives faster than anything you control.
These come from scenario modeling, which is where the dates and sizes are already collected. The test is how the scenario gets verified rather than assumed.
3. Test the Event, Not the Average
The load model for a pre-launch test is the event's shape, which is usually nothing like normal traffic.
- Use the previous comparable event if one exists. Its actual arrival curve is better than any estimate.
- Model the peak minute, not the day's total — see realistic traffic modeling.
- Include the journey the event drives. A campaign sends everyone to one landing page and then through one signup flow, which is a far narrower path than normal traffic and concentrates load on a few endpoints.
- Test the success case. A campaign that works twice as well as expected is a real outcome and is never the number in the plan.
4. Agree the Exit Criteria Beforehand
Without a threshold set in advance, a result is negotiated afterwards against a launch date that everyone is already committed to, and it loses.
- Write the criteria before the test: the load it must sustain, the acceptable 95th percentile, the acceptable error rate, the required recovery time.
- Name who decides if they are not met, and what the options are — delay, reduce scope, add capacity, or proceed with a documented risk.
- Proceeding is a legitimate choice, when made deliberately and with the risk recorded. The failure is proceeding because the result arrived too late to matter.
5. Have a Plan for Being Wrong Anyway
A passed test reduces risk and does not remove it. The event will differ from the model in some way nobody predicted, so the day itself needs preparing too.
- Someone watching, who knows what the test predicted and can see the divergence.
- The degradation controls from breaking point identification ready to use: what gets shed, at what threshold, by whom.
- A rollback or a scale-up that has been rehearsed, not merely written down.
- A freeze on unrelated changes for the window, so a surprise has one fewer possible cause.
6. Record It Against the Outcome
After the event, put the actual load beside the modelled one. Over a few events this becomes the most valuable capacity artefact you own: a measured relationship between “marketing expects this many” and what actually arrived.
It also settles the recurring argument about whether these tests are worth the effort, in whichever direction the evidence points.
How We Approach It
- Work backwards from the event date to a test date that leaves room to fix, re-test and deploy.
- Model the event's own shape, from the last comparable one where possible, including the narrow path it drives users down.
- Agree the exit criteria and the decision owner before running anything.
- Run it, fix what it finds, and run it again. The second run is the one that matters.
- Prepare the day: monitoring, shedding thresholds, a rehearsed scale-up, a change freeze.
- Compare actual against modelled afterwards, and keep it.
What You Get
- A test date derived from the event date and the time needed to act, rather than from whenever there is a gap.
- A load model built from the event's own shape, including the success case.
- Exit criteria and a named decision owner agreed before the result exists.
- A readiness plan for the day: what to watch, what to shed, and what has been rehearsed.
- Modelled against actual recorded afterwards, so the next event is estimated from evidence.
The question worth asking of the next big date in the calendar: what load does it bring, who decided that number, and when is it being tested?