Realistic Traffic Modeling
Back to Performance Tuning and Capacity Planning · Breaking Point Identification · Controlled Environment · Pre-Launch Validation · Service Offerings
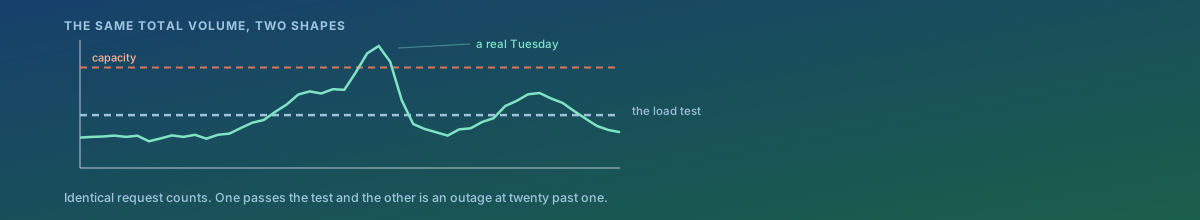
Load patterns based on actual usage shapes — bursty, sustained, or spiky — not just a flat ramp-up that misses how real traffic arrives. The illustration above is the whole argument: two days carrying exactly the same number of requests, one of which is a comfortable pass and the other an outage at lunchtime.
1. Capacity Is Consumed by the Peak
Averages are a property of the report; the system experiences the busiest minute. A service handling two million requests a day sounds like 23 per second, and if a third of them arrive in two hours the real figure is several times that.
Measure your peak-to-average ratio once and it will keep being useful. For a consumer service it is commonly three to five; for anything driven by notifications it can be far higher, because everyone is told at the same moment.
2. What a Flat Test Never Exercises
- Cold starts and autoscaling. A steady ramp gives every layer time to warm and scale. Real traffic does not, and the interesting failures happen during the gap between the spike and the capacity arriving.
- Queue build-up and drain. A burst creates a backlog, and whether the system recovers or stays behind is the single most useful thing a test can tell you.
- Cache behaviour. A flat test repeating the same requests achieves an unrealistically high hit rate and so never loads the database properly — see caching strategy.
- Connection pool exhaustion, which is a burst phenomenon. Steady load rarely reaches it; a spike reaches it immediately.
- Timeouts and retries. Under a burst, slow responses trigger client retries, and the retries are additional load exactly when there is least room for them.
3. The Mix Matters as Much as the Shape
A test that hammers one endpoint measures that endpoint. Production is a mixture, and the expensive requests are usually a small fraction of it — which is precisely why they get left out of the model.
- Take the mix from the access log, weighted by actual frequency, including the five per cent that are reports and exports.
- Vary the data. Every virtual user requesting the same record tests one cache entry. Real users spread across the dataset and miss far more often.
- Include the unauthenticated traffic — crawlers, health checks, scanners. It is real load and it does not stop during your peak.
- Include writes. A read-only test on a system that writes is measuring a different system, because writes take locks and invalidate caches.
4. Think Time, and the Mistake It Causes
Real users pause between actions. A test without think time has each virtual user hammering continuously, so a hundred virtual users generate the load of several thousand real ones — and the result is read as “we fail at a hundred users”, which is alarming and meaningless.
The honest unit is requests per second, not virtual users. Where user counts are wanted, derive them from the measured session behaviour rather than assuming one request per user per second.
5. The Shape Is Already Recorded
None of this needs to be invented. A week of access logs or a month of request-rate metrics contains the daily curve, the weekly one, the peak-to-average ratio, the endpoint mix and the arrival pattern of your worst burst.
- Pick a representative busy day, and separately the worst day in the record.
- Model both — the typical peak and the known extreme.
- Where a past event is relevant, replay its actual shape rather than approximating it. See scenario modeling.
How We Approach It
- Extract the real shape from logs or metrics: daily curve, peak-to-average ratio, and the sharpest burst on record.
- Extract the real mix, weighted by frequency and including the expensive minority, the writes and the background traffic.
- Parameterise the data so virtual users do not all request the same rows.
- Model think time from observed sessions, and report in requests per second.
- Run the typical peak and the known extreme, and watch recovery after the burst as well as behaviour during it.
- Compare the test's own metrics against production's — cache hit rate, error rate, request mix — to confirm the model resembles reality.
What You Get
- A load model derived from your own traffic: shape, mix, data distribution and think time.
- Your peak-to-average ratio as a number, which is reusable in every capacity conversation afterwards.
- Results for both a typical peak and your worst recorded burst, including how long recovery took.
- A check that the test resembles production, rather than an assumption that it does.
- The model kept as configuration, so the next test is a re-run and not a rebuild.
The question that exposes most load tests: during the test, what was the cache hit rate? If it was far above production's, the database was never really tested.