Evidence Before Action
Back to Performance Tuning and Capacity Planning · End-to-End Profiling · Resource Utilization Breakdown · Slow Query Identification · Service Offerings
Optimizing what profiling actually shows is slow, not whatever seems like the obvious suspect. This is the least technical item on the list and the one that decides whether the others were worth doing.
1. The Complicated Code Is Rarely the Expensive Code
Intuition points at whatever was hardest to write. That instinct is close to useless, because difficulty and cost are unrelated: the nested loop someone laboured over runs once per request on a small list, while the innocuous helper called from a template runs four hundred times.
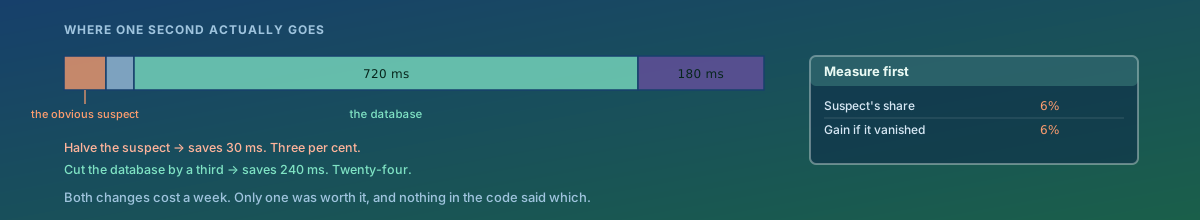
The illustration above is the shape this usually takes. The clever algorithm everyone suspects is 60 ms of a one-second request. Halving it saves 30 ms. Deleting it entirely saves six per cent, and that is the ceiling — no amount of work on it can do better. The database, which nobody proposed touching, is 720.
2. The Arithmetic That Sets the Ceiling
Amdahl's law in its practical form: the most any optimisation can gain is the share of total time it occupies. Before changing anything, the only number needed is that share.
| Component's share | Make it twice as fast | Make it instant |
|---|---|---|
| 5% | 2.5% faster overall | 5% |
| 20% | 10% | 20% |
| 50% | 25% | 50% |
| 80% | 40% | 80% |
A week spent doubling the speed of something that is five per cent of the request buys 2.5 per cent. The same week spent on the eighty per cent component, for a far more modest improvement, buys several times more. The measurement that tells you which column you are in takes an hour.
3. The Discipline
- Record the baseline before touching anything, measured the way you will measure afterwards. A baseline taken differently is not a baseline.
- Change one thing. Two changes at once and an improvement tells you nothing about which caused it — or that one helped while the other hurt.
- Measure under the same conditions. Same data volume, same concurrency, same cache state. A query is fast or slow on a particular machine in a particular state, not in the abstract.
- Write down the prediction first. “This should take the page from 900 to about 700 ms.” Being wrong about that is information; noticing you were wrong is the whole point.
- Keep what the numbers were. Six months later, the question is whether the regression is new, and only a recorded figure answers it.
4. “It Feels Faster”
It usually does, to the person who made the change. They know what to look at, they have a warm cache, and they are predisposed. This is not carelessness; it is how perception works, and it is the reason the step after a change is a measurement rather than an impression.
The same applies in reverse to the original complaint. “The system feels slow” is a real report and a poor specification — it may be one endpoint, one time of day, one customer's data volume, or the network between the user and the server. Turning it into a measurement is the first piece of work, not a preliminary to it. See resource utilization breakdown.
5. What an Unnecessary Fix Costs
Acting without evidence is usually described as wasted effort. The waste is the smaller part.
- The complexity stays. A cache added for a problem that was not there is a cache that must now be invalidated correctly, forever, by everyone who touches that code.
- It is never removed, because nobody can prove it is not load-bearing.
- It obscures the next investigation. The real bottleneck is now behind a layer that was added to fix it.
- It teaches the wrong lesson. If things improved for unrelated reasons, the unnecessary change gets credit and gets repeated.
6. Being Wrong Is the Normal Case
We get this wrong too, and the only defence that works is checking rather than reasoning harder. Three from our own work, all caught by measurement:
- A statistics page took 58 seconds on one host and was instant on another — same code, same data. The difference was page cache, not anything in the query.
- A search of the codebase reported five pages missing a required statement. Reading them showed three said it in their own words. The grep was the wrong instrument, and acting on it would have produced duplicates.
- A network setting was declared absent after reading one host's configuration. It had been present on the other all along, and the correction cost more than checking would have.
None of these were failures of care. They were conclusions drawn one step before the evidence arrived.
How We Approach It
- Turn the complaint into a measurement — which endpoint, which percentile, under what load.
- Profile before proposing anything, and produce the breakdown of where the time goes.
- Compute the ceiling for each candidate change, so effort goes where it can pay.
- Change one thing, predict the result, measure it, and record both.
- Discard changes that did not help, rather than keeping them because they seemed sensible.
- Leave the measurement in place, so the next regression announces itself.
What You Get
- The complaint restated as a number, with the conditions under which it reproduces.
- A breakdown of where the time goes, and the maximum each candidate change could gain.
- Changes made one at a time, each with a prediction, a result, and a note where the two disagreed.
- Anything that did not help removed again, so the codebase does not accumulate fixes for problems it did not have.
- The baseline and the instrumentation left behind, which is what makes the next question cheaper than this one.
The habit this protects is simple and easily lost under pressure: before changing anything, be able to say what fraction of the problem it is.