Slow Query Identification
Back to Performance Tuning and Capacity Planning · End-to-End Profiling · Resource Utilization Breakdown · Evidence Before Action · Service Offerings
Pulling the actual worst-performing database queries, often the single biggest win available. It frequently is the biggest win, and the reason is simple: application code runs on your CPU, while a bad query makes the database do work that no amount of application tuning can avoid.
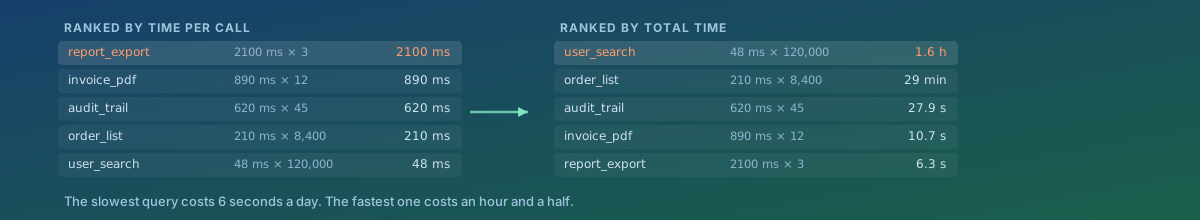
1. Rank by Total Time, Not by Time per Call
This single choice decides whether the exercise finds anything. A slow query log sorted by duration shows you the two-second report that runs three times a day. Sorted by total time, the same data shows a 48-millisecond query run a hundred and twenty thousand times — six seconds of database work against an hour and a half.
The fast query is also the easier fix, which is the part people find surprising. It runs constantly, so any improvement compounds; and queries that run that often are usually simple enough that an index settles them.
Where to get the ranking:
- PostgreSQL — the
pg_stat_statementsextension, which aggregates by normalised query text and gives total time, calls, mean and rows directly. - MySQL and MariaDB — the slow query log with a low threshold, summarised
rather than read line by line, or
performance_schemafor the same aggregation without a log file. - SQL Server — Query Store, which keeps per-plan totals and also shows when a plan changed underneath you.
- SQLite — no built-in equivalent, so instrument at the application.
2. Read the Plan, and Read the Right One
EXPLAIN shows what the planner intends. EXPLAIN ANALYZE runs the query
and shows what happened, and the answer is usually in the difference between the two.
- Estimated rows against actual rows. When the planner expects 20 and gets 200,000, it chose a nested loop that would have been right for 20. The query is not slow because of the join; it is slow because the statistics were wrong.
- A sequential scan is not automatically the problem. On a small table it is the correct choice, and forcing an index there makes things worse.
- Look for the operation that dominates the time, not the one that looks complicated. They are frequently different nodes.
- Check whether a sort spilled to disk, which turns a fast query into a slow one with no change to the SQL.
3. Why an Index Is Not Being Used
An index exists and the plan ignores it. Almost always one of these:
- A function wraps the column.
WHERE lower(email) = ?cannot use an index onemail; it needs one onlower(email). - The types do not match, so the database casts the column and the index no longer applies.
- A leading wildcard.
LIKE '%foo'has nothing to seek to. - Wrong column order in a composite index. An index on (a, b) serves a query filtering on a, and does nothing for one filtering only on b.
- The planner is right. If the query returns a third of the table, reading it sequentially genuinely is faster.
4. The Problem a Slow Query Log Cannot Show You
N+1 is invisible to every tool in section 1, because each individual query is fast. One query fetches fifty rows, then the ORM issues fifty more to load a relation, and the log records fifty-one unremarkable entries.
It only appears as volume: a query with an absurd call count relative to the number of page views. That is also how to find it — divide calls by requests and look for anything above one. Fixing it is usually an eager-load hint rather than anything to do with the database.
The same blindness applies to a query that is fast alone and slow under concurrency, because it holds a lock. That one shows up in lock-wait statistics, not in query duration.
5. Every Index Is a Trade
Adding an index is not free, and the cost is paid by a different part of the system from the one that benefits. Each index must be updated on every insert, update and delete to its columns, it occupies space, and it needs maintaining. A table with twelve indexes has slow writes for a reason.
- Check whether an existing index can be extended rather than a new one added.
- Look for indexes nothing uses — most databases will tell you, and removing them is a free write speed-up.
- Measure the write path after adding one, not only the read path.
6. A Worked Example From Our Own Infrastructure
A statistics page on one of our tools took 58 seconds to load, and the cause was a single
SELECT count(*). In SQLite that is a full table scan, and the table had grown past
fourteen gigabytes. No index helps; counting is the work.
The fix was not query optimisation at all — it was storing the count when the data is written and reading it back. 58 seconds became 0.002.
The part worth carrying away is why it went unnoticed. The same query was fast on one host and slow on another, with the same data and the same code, because one had the table in page cache and the other did not. A query is not fast or slow on its own; it is fast or slow on a particular machine in a particular state, which is why the measurement has to happen where the problem is.
How We Approach It
- Turn on the right collector for your database and let it gather over a representative period, including a busy one.
- Rank by total time, and separately by call count relative to request volume, which is what surfaces N+1.
- Take the top few and read their plans with timings, looking first at the gap between estimated and actual rows.
- Establish why — missing index, unusable index, stale statistics, a spilled sort, a lock — rather than applying the usual remedy.
- Change one thing and measure the same way, including the write path if an index was added.
- Leave the collector running, so the next regression is visible without another engagement.
What You Get
- Your queries ranked by what they actually cost, with the call counts that explain the ranking.
- An N+1 report, which standard tooling does not produce and which is frequently the largest single item.
- For each of the worst, the plan, the reason, and the specific change — not a general recommendation to add indexes.
- Before-and-after figures for every change, read and write.
- The collection left in place, so this is a baseline rather than a snapshot.
The test of this work is whether the thing you fix is the thing that was costing you. Ranked by duration, it usually is not.