Resource Utilization Breakdown
Back to Performance Tuning and Capacity Planning · End-to-End Profiling · Slow Query Identification · Evidence Before Action · Service Offerings
CPU, memory, disk I/O, and network measured separately, since “the server feels slow” usually means one specific resource is maxed out. The separation is the work. A single overall impression cannot be acted on, and the four resources fail in ways that look nothing alike.
1. Utilisation Is the Wrong Column
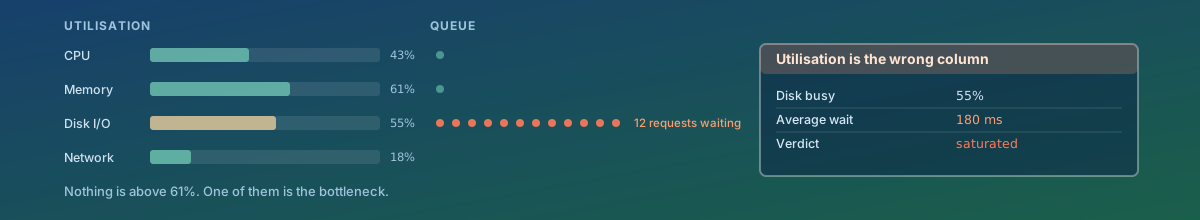
The illustration above is the ordinary case: nothing is above 61 per cent, and one of them is the bottleneck anyway. Utilisation answers “how much of the time was it busy”, and a device can be busy half the time while every request waits behind a queue.
The question that identifies a bottleneck is saturation: how much work is waiting. A disk at 100 per cent utilisation with nothing queued is keeping up exactly. A disk at 55 per cent with twelve requests waiting is not, and only the second number says so.
Errors are the third column and the one most often missing entirely — retransmits, dropped packets, failed allocations, I/O errors. A resource that is quietly failing and retrying looks like a resource that is merely slow.
2. What Each Resource Actually Needs Measured
| Resource | Useful | Misleading on its own |
|---|---|---|
| CPU | Per-core utilisation, run-queue length, time stolen by the hypervisor, time waiting on I/O | The overall percentage. Four cores at 40 per cent can be one core pinned and three idle, which a single-threaded workload experiences as 100 |
| Memory | Reclaim pressure, swap in and out rates, page faults, whether the OOM killer has run | Free memory. Linux spends free memory on page cache deliberately, so a healthy machine reports almost none |
| Disk | Latency per operation, queue depth, IOPS and throughput separately, read against write | Throughput alone. A device can be far from its megabytes-per-second limit and saturated on operations per second |
| Network | Retransmits, connection setup time, DNS resolution time, socket queue overflows | Bandwidth used. It is rarely the constraint; latency and connection handling usually are |
Load average deserves its own warning. On Linux it counts processes that are runnable and processes in uninterruptible sleep, which mostly means waiting on disk. A load average of 12 on a 4-core machine might be a CPU problem or might be a storage problem, and the number alone cannot tell you which.
3. Averages Hide the Thing You Are Looking For
A one-minute average is a poor instrument for a problem that lasts eight seconds. If requests time out at five seconds, a spike shorter than your sampling interval is invisible — and spikes of exactly that length are the common case, because they are what a queue draining looks like.
- Sample fast enough to see the failure. If the symptom lasts seconds, a minute-resolution graph will show a gentle bump at most.
- Keep percentiles, not just means. A mean response time of 200 ms is consistent with everything being fine and with one request in fifty taking four seconds. The 95th and 99th percentiles distinguish them.
- Keep the peak when you downsample. Rolling up to hourly averages for retention is sensible; discarding the maximum in the process destroys the evidence.
4. Measure Where the Workload Is
- In a container, host metrics describe the host. The process sees cgroup limits, and a container throttled at its CPU quota shows a perfectly calm host.
- On a virtual machine, ask about steal time. CPU taken by the hypervisor for someone else appears as your machine being slow with no local cause.
- On shared storage, the neighbours are part of your latency. Local metrics will not show why.
- Measure at the application too. Time spent waiting on a connection pool or a lock is invisible to every system metric, and is a resource constraint all the same — see end-to-end profiling.
5. The Constraint Is Usually Specific and Dull
Two from our own infrastructure, both found by measuring rather than guessing. One host runs on a single core with 5.5 GB and spends a third of its memory in swap, which means anything CPU-bound queues behind everything else and the fix is scheduling rather than optimisation. Another has an uplink that sustains about 0.4 MB/s, which decided what gets replicated between them — and an incremental transfer turned out to cost nothing in steady state, which the raw bandwidth figure would never have suggested.
Neither was visible from a general impression. Both changed what we built.
How We Approach It
- Establish utilisation, saturation and errors for all four resources, at a sampling rate fine enough to see the symptom you are actually chasing.
- Measure at the right layer — cgroup rather than host inside a container, and with steal time where the machine is virtual.
- Separate the numbers that get conflated: per-core from aggregate, IOPS from throughput, latency from utilisation, free memory from reclaim pressure.
- Reproduce the slow period and look at what was saturated during it, not at what is saturated now.
- Name one constraint, with the measurement that identifies it, and hand it to the work that follows.
What You Get
- Utilisation, saturation and errors for CPU, memory, disk and network, measured where the workload actually runs.
- Percentiles and peaks retained, not just averages, at a resolution that can see the symptom.
- The specific resource that is constraining you, named, with the numbers that show it.
- The misleading readings called out explicitly — load average, free memory, aggregate CPU — so they stop being used as evidence.
- A baseline to measure any later change against.
The deliverable is one sentence with a number in it. Not “the server is under load”, but “the disk is saturated at 180 ms average wait while running at 55 per cent utilisation, and that is where your response time is going”.