Log Aggregation
Back to Server Setup · Resource Monitoring · Root Cause Diagnosis · Monitoring & Logging Solutions
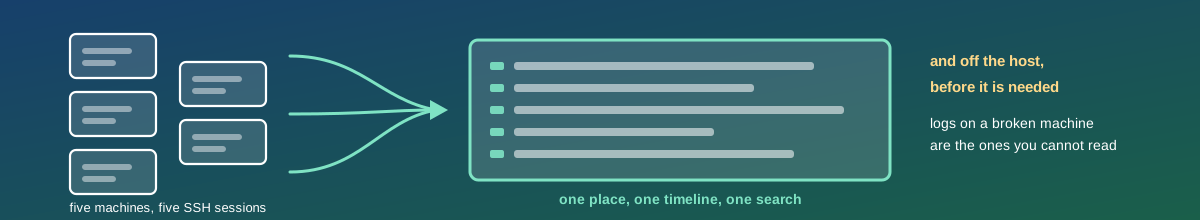
Centralized logs so troubleshooting doesn't mean SSH-ing into five different machines during an incident. The convenience argument is real, but it is the smaller one. The larger ones: logs on a host that has failed may be unreachable, and logs on a host that has been compromised are the first thing an intruder edits. Shipping them off is a resilience and integrity measure that happens to also be convenient.
1. Ship Everything Off, Immediately
- Application logs, system logs, and the ones in between — web server access and error logs, database slow queries, authentication events, firewall denials, scheduled-job output. The gaps are usually the interesting ones.
- As it is written, not on a schedule. A batch every fifteen minutes is fifteen minutes you cannot see during an incident, and fifteen minutes that can be lost with the host.
- Keep a local copy briefly so the shipper can catch up after a network interruption rather than losing that window entirely.
- Containers write to standard output, and the platform collects it. Logging to a file inside a container means the logs are deleted with it.
2. Structure Beats Parsing
A log line written as a sentence has to be parsed with a regular expression, and that expression breaks the next time someone edits the message. Logging as structured data — key-value or JSON — means fields are queryable directly.
What every event should carry: an accurate timestamp with a timezone, the host and the service, a severity level, and an identifier for the request. The timestamp matters more than it sounds — correlating across machines is impossible if their clocks disagree, which is why time synchronisation belongs in the base build.
The correlation ID
The single highest-value change available in most systems: assign an identifier to each incoming request, pass it through every service and every log line it touches, and return it to the client. Then one search reconstructs the entire path of a single request across every machine. Without it, tracing one user's failed transaction through four services is guesswork with timestamps. With it, a customer can quote the reference from their error page and you have the whole story in seconds.
3. Levels, and What Not to Log
Use severity levels consistently — debug for development, info for normal operation, warn for recoverable problems, error for failures needing attention. The common failure is everything at one level, which makes filtering impossible. Log volume should also be adjustable without a redeploy, so debug can be turned on during an incident and off afterwards.
Logs inherit every obligation attached to what is in them, so keep secrets and personal data out. No passwords, tokens, card numbers, full request bodies containing personal data. This is not fastidiousness: a log store is widely readable within a company, is retained for a long time, and is subject to the same residency and erasure rules as any other copy of the data — see security and compliance needs. Redact at the source, because redacting later means it was already stored.
4. Retention, and the Bill
Log storage grows without limit and centralised logging is one of the easier ways to spend money by accident. The approach that works:
- Tier it. Recent logs hot and instantly searchable; older logs in cheap archival storage, slower to query and far cheaper to keep.
- Set retention by obligation and by usefulness — security and audit logs usually need to be kept far longer than debug output, and compliance may set the number for you.
- Drop the noise at the source. Health-check requests hitting the access log every second are pure volume. Filter before shipping, not after paying.
- Make security logs immutable. Append-only storage, and access to the log platform itself logged, so the audit trail means something.
5. It Has to Be Searchable Under Pressure
The test of a logging system is not whether it holds the data; it is whether someone can find something at 03:00 while a service is down. That means searches that return in seconds rather than minutes, saved queries for the common questions, and a few alerts driven by log content — a spike in error rate, a burst of authentication failures, a specific exception appearing. Those catch a class of problem that resource monitoring never sees.
And keep it independent. A logging platform that runs on the infrastructure it monitors is unavailable precisely when it is needed.
What You Get
- Log shipping from every host and container, with a local buffer for network interruptions.
- Structured events with consistent fields, synchronised clocks, and correlation IDs threaded through the request path.
- Redaction at the source for secrets and personal data.
- Tiered retention set against obligations, with noise filtered before it is stored.
- Saved searches and content-based alerts, on a platform that survives the estate it watches.