Root Cause Diagnosis
Back to Server Setup · Incident Handling · Log Aggregation · Request Profiling
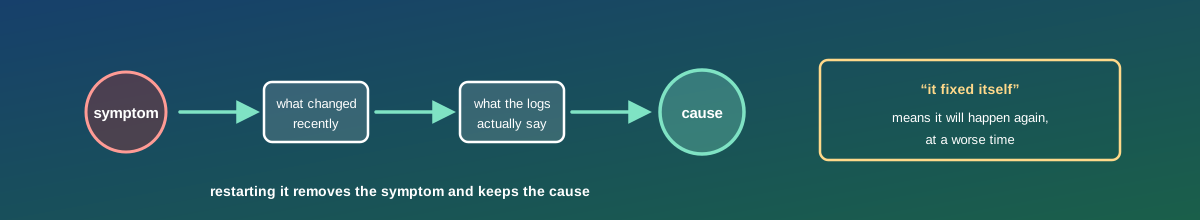
We dig into logs, metrics, and recent changes to find why something broke, not just restart it and move on. A restart usually removes the symptom and always keeps the cause, which is why the same incident returns — generally at a worse moment, because the conditions that produced it are more likely under load.
1. Restore First, Diagnose Second
Worth stating plainly, because it is the opposite of what this page is about. During a live outage, getting the service back takes priority over understanding it. What matters is preserving the evidence while you do: capture the logs, take a copy of the state, record the metrics and note the time, before restarting the thing that would have told you what happened.
Restarting without capturing anything is the choice that guarantees the investigation cannot happen. It takes two minutes to avoid.
2. Start With What Changed
Systems that have been working for months rarely break spontaneously. The first question is always what changed, and the honest answer is usually broader than “we deployed”:
- Deployments and configuration changes — yours and other teams'.
- Infrastructure changes: a firewall rule, a DNS record, a certificate, a scaling event.
- Automatic changes: an unattended update, a rotated credential, a scheduled job that runs monthly and ran last night.
- External changes: a provider's maintenance, an upstream API's new behaviour, a partner's release.
- Data changes: an import, a volume of traffic that crossed a threshold, one unusually large record.
- And time itself — certificates expire, licences lapse, disks fill, counters wrap. These break with no change at all, which is why they are so confusing.
A change log correlated against the moment the symptom started answers a great many incidents before any deeper work begins.
3. Follow the Evidence, Not the Hypothesis
The characteristic failure of troubleshooting is settling on an explanation early and then looking only for support for it. The method that avoids it:
- Establish the timeline precisely. When did it start, what else happened at that moment. This is where aggregated logs with synchronised clocks and correlation IDs pay for themselves.
- Narrow the scope. All users or some? All requests or one endpoint? One host or every host? Each answer eliminates whole categories of cause.
- Work down the stack — application, runtime, database, operating system, network, hardware — rather than jumping to the most interesting layer.
- Reproduce it if you can. A fault you can trigger on demand is one you can definitively confirm fixed. A fault you cannot reproduce is one you can only hope is fixed.
- Change one thing at a time, even under pressure. Three simultaneous changes that restore service leave you not knowing which mattered, and two of them may now be causing something else.
4. Keep Asking Why
The first cause found is rarely the useful one. “The disk filled” is a finding, not a cause. Why did it fill — a log stopped rotating. Why did rotation stop — a configuration change omitted that file. Why did nobody notice — there was no alert on disk growth.
Each level suggests a different fix, and the later ones are more durable: clearing the disk solves today, fixing rotation solves that file, alerting on growth solves the whole category. Stop when the remaining answers stop being actionable — the aim is a fix you can make, not a philosophical origin.
It is also worth resisting the pull towards a single cause. Serious incidents usually need several things to be true at once: a latent bug, an unusual input, and a monitoring gap that let it run. Fixing one of the three is enough to prevent recurrence, and knowing all three tells you which one is cheapest to fix.
5. When Not to Chase It
Diagnosis costs time, and not every incident earns it. A one-off glitch on a development machine does not need a formal investigation. The judgement we apply: chase it if it happened in production, if it could recur, if it affected customers or data, or if nobody can explain it. A problem nobody understands will happen again and nobody will recognise it.
And where we cannot find the cause, we say so rather than inventing a plausible one. The appropriate response to an unexplained incident is added instrumentation, so that the next occurrence produces the evidence this one did not — which is a real outcome, and a more honest one than a guess.
What You Get
- Evidence captured before the fix, so the investigation remains possible.
- A timeline correlating the symptom with every category of change.
- A cause traced far enough to produce a durable fix, with contributing factors named separately.
- A written explanation of what happened, in language you can pass on.
- Where the cause is genuinely unknown, an honest statement and the instrumentation to catch it next time.