Cable and Port Documentation
Back to Data Center Management · Asset Tagging · Rack Elevation Diagrams · CMDB · Service Offerings
Cable and port documentation means knowing what connects to what without needing to physically trace it during an incident. That qualifier is the whole justification. Tracing a cable by hand is perfectly possible — it is just that the moment you need to is the moment you can least afford the twenty minutes, and it is usually being done by torchlight behind a rack with someone on a call asking for updates.
1. Record the Port, Not the Cable
The instinct is to inventory cables. It is the wrong unit. Cables are interchangeable and get replaced; ports are fixed, addressable and few. A record organised by port answers the questions people actually ask — what is on switch port 12, where does this server's second NIC go, is this panel port in use — and it cannot drift into counting the same cable twice.
Each connection is then a row with two endpoints, each endpoint being an asset tag plus a port identifier, and the properties of the link itself alongside: speed, media, VLAN or purpose.
2. A Patch Panel Is a Hop, Not a Pass-Through
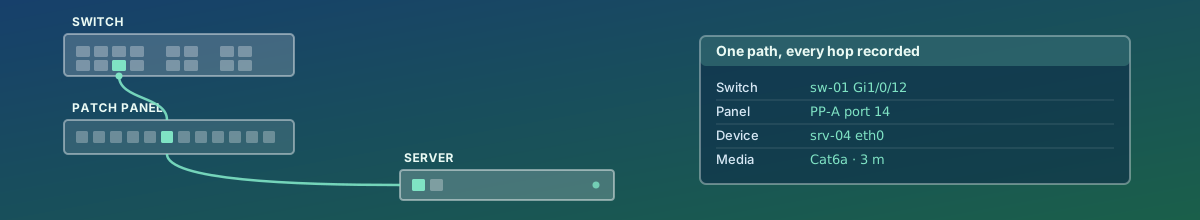
Structured cabling means most links are not one cable. A server connects to a patch panel, the panel is trunked to the switch, and the logical path server to switch is physically three components. Documentation that records only the logical endpoints is useless for the one job it exists to do, because it cannot tell you which physical thing to go and touch.
Record every hop, as the illustration above does:
| Hop | Recorded as |
|---|---|
| Device port | Asset tag plus interface name, e.g. srv-04 eth0 |
| Patch panel port | Panel identifier plus port number, in both the near and far panel where there are two |
| Switch port | Switch asset tag plus the interface as the switch itself names it |
| The link | Media and category, connector, length, and what it carries |
For fibre, media detail is not optional: type and mode (OM4, OS2), connector (LC, MPO), polarity, and length. A link that will not come up is very often a polarity or mode mismatch, and the record is how that is diagnosed without swapping parts at random.
3. Label Both Ends, and Encode the Other End
- Every cable labelled at both ends. One label is half a record, and it is always the far end you are standing at.
- The label names the other end. A label reading only "eth0" tells you nothing you could not already see. One reading the destination device and port turns a trace into a glance.
- One scheme, applied consistently, so a label can be read by someone who has never seen your estate before.
- Labels that survive. Wrap-around or flag labels rated for the environment. A label that falls off behind a rack is not noticed until it is needed.
4. Power Cabling Is Part of This
Network cabling gets documented far more often than power, and power is where the more consequential mistake hides. For every device, record which PDU and which outlet each cord goes to.
The reason is feed diversity. Dual-PSU hardware exists to survive the loss of one supply, and it only does so if the two cords are genuinely on separate feeds. Both in the same PDU is a configuration that looks correct from the front of the rack, passes casual inspection, and fails exactly when it was supposed to help. Documented outlets make it checkable — and make it visible on the rear rack elevation.
Documented outlets also make a PDU swap or a circuit maintenance window plannable, because you know precisely what goes dark.
5. Document the Out-of-Band Path First
Console servers, IPMI and iDRAC addresses, and the management network are what you reach for when the production path is down — which is to say, at the exact moment the documentation is hardest to get to. Record them, keep a copy that does not depend on the network being up, and verify the path occasionally. An out-of-band route nobody has tested is a route you find out about during the incident. This is the same argument made in disaster recovery planning.
6. Let Discovery Check Your Work
Switches know a great deal about what is plugged into them. LLDP (or CDP on Cisco equipment) reports neighbours; MAC address tables and ARP show what is live on each port; interface counters show which ports are actually connected.
Use this to verify the documentation, not to replace it. Discovery is an excellent auditor and a poor record, because it cannot see:
- Patch panels and every other passive element, which is most of the physical path;
- Power cabling, which has no protocol at all;
- Console and serial connections;
- Unmanaged devices, and anything currently powered off;
- Intent — what a port is for, and why that cable was run.
The practical arrangement is a periodic reconciliation: pull neighbours from every switch, compare against the record, and review the differences. Each difference is either an undocumented change or a documentation error, and both are worth knowing. The count of mismatches is the health metric for the whole exercise, in the same way the discrepancy rate is for asset tagging. Tooling that already does this fits alongside your monitoring and network configuration monitoring.
7. Where It Pays Off
- Incidents. A link is down and you know which port, which panel and which cable before anyone walks to the room. See root cause diagnosis.
- Change safety. Knowing what a port carries before unplugging it. Most accidental outages during maintenance are this.
- Remote hands. Precise instructions to someone who cannot see what you see.
- Capacity. How many switch ports and panel ports are genuinely free, without a counting exercise.
- Decommissioning. Pulling every cable belonging to a removed device instead of leaving three in place for the next person to puzzle over.
How We Approach It
- Pull what discovery already knows — LLDP neighbours, MAC tables, interface state — as the starting skeleton.
- Walk the physical path for what discovery cannot see: patch panels, power, console, passive and powered-off equipment.
- Agree a labelling scheme and label both ends of everything, including power.
- Record port-first, with every hop, and the media details that matter for fibre.
- Check feed diversity across all dual-PSU hardware and report what is not genuinely redundant.
- Set up reconciliation against discovery on a schedule, with the mismatch count as the metric.
What You Get
- A port-first record of every connection, with each hop from device to panel to switch.
- Both ends of every cable labelled, each label naming its far end.
- Power cabling documented to the outlet, with a report of every dual-PSU device not actually on two feeds.
- The out-of-band path written down and verified, in a form that survives the network being down.
- A reconciliation procedure against LLDP and friends, and the first mismatch count as a baseline.
The test of this work is simple: during the next incident, does anyone need to trace a cable by hand? If the answer is no, the documentation is doing its job.