Post-Incident Follow-Up
Back to Server Setup · Incident Handling · Root Cause Diagnosis · Resource Monitoring
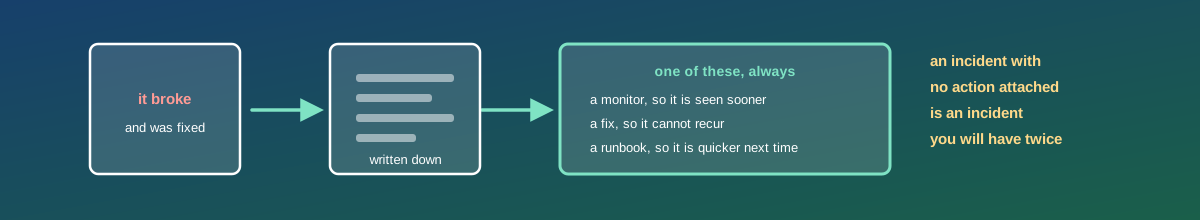
After resolution, we document what happened and put in place whatever prevents it from recurring — a monitor, a config fix, a runbook. This is the step that gets skipped, because by the time it is due the crisis has passed and something else is urgent. Skipping it is also what turns one incident into a recurring one.
1. Write It Down While It Is Fresh
Within a day or two, not a fortnight. The write-up is short and factual:
- What the impact was — who was affected, for how long, and what they could not do. In business terms, not only technical ones.
- The timeline — when it started, when it was detected, when someone started work, when service was restored. The gap between started and detected is frequently the most useful number in the whole document.
- What caused it, and the contributing factors separately — see root cause diagnosis.
- What was done, including mitigations that are still in place and need removing.
- What we would have wanted and did not have: a metric, a log line, an access route, a runbook.
2. Blameless, Because the Alternative Does Not Work
Where a review looks for who made the mistake, people stop reporting near-misses and stop being candid about what they did — and the information dries up exactly where it is most useful. The productive question is not who typed the command but why the system allowed a single typed command to cause this, why nothing caught it, and why it took so long to notice.
That is not an absence of accountability. Actions are owned, dates are real, and follow-up is tracked. It is a statement about where to look: at the conditions, because those are what can be changed.
3. Every Incident Produces at Least One Action
If the honest conclusion is “nothing to do”, the review was not thorough enough. There is always something, and it usually falls into one of these:
- A monitor, so next time it is detected in two minutes rather than by a customer in forty. Almost every incident yields one of these, and they are cheap — see resource monitoring and uptime checks.
- A fix that removes the cause, or a guard that stops the condition arising.
- A runbook, so the next person resolves it in ten minutes instead of rediscovering it. Written during the incident where possible, because that is when the detail is known.
- Better logging or instrumentation, where the diagnosis was slow for want of evidence — the correct outcome when the cause could not be found at all.
- A process change — a staged deployment, a check before a risky operation, a corrected escalation contact.
Each action gets one named owner and a date. Actions owned by a team are owned by nobody.
4. Track Them, or the Review Was Theatre
The most common way this fails is not a bad review but a good review whose actions were never done. So the actions go into the same tracker as everything else, with the same visibility, and they get reviewed at the next one. An incident recurring with an outstanding action from the last time is a useful and uncomfortable signal, and it should be visible rather than quietly noted.
Be realistic about prioritisation, too. Not every action justifies its cost, and it is more honest to record that a fix was considered and deliberately deferred, with the reason, than to leave it open forever. A deferred decision is a decision; a forgotten one is not.
5. Look Across Incidents, Not Just Within Them
Each incident individually may look like bad luck. Read a quarter of them together and patterns appear that no single review shows: most incidents following deployments, one component appearing repeatedly, detection consistently slow, the same undocumented knowledge being needed each time. Those patterns point at systemic fixes — better release practice, one component that needs rebuilding, a monitoring gap — which are worth far more than the individual actions.
And the numbers worth tracking over time are how long detection takes, how long resolution takes, and how many incidents recur. If detection is not improving, the monitors from the last ten reviews were not the right ones.
What You Get
- A written incident report within days, with impact stated in business terms and a timeline that exposes the detection gap.
- A blameless review focused on conditions rather than individuals.
- At least one concrete action per incident, each with a named owner and a date.
- Actions tracked visibly, with deferrals recorded as decisions rather than left open.
- A periodic look across incidents for patterns, and trend figures for detection, resolution and recurrence.