Performance Tuning
Back to Server Setup · Workload Requirements · Capacity Planning · Request Profiling
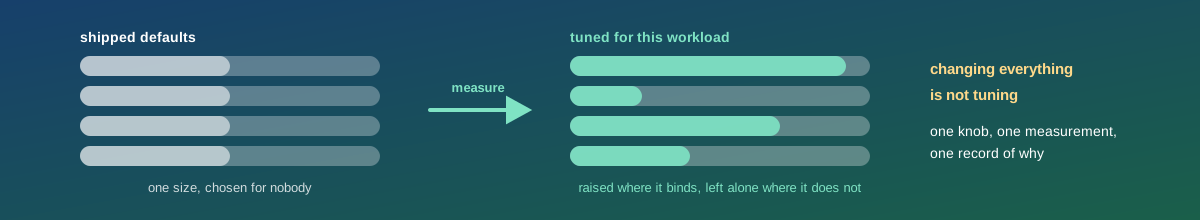
Kernel parameters, connection limits, and caching configured for the actual workload rather than left at generic defaults. Defaults are chosen to be safe on an unknown machine — a laptop, a container, a large database server — which means they are rarely right for any of them. Build-time tuning closes the obvious gaps; ongoing work belongs to capacity planning.
1. The Method Matters More Than the Settings
Most tuning advice found online is a list of values to paste in. That approach produces systems nobody understands and occasionally makes things worse. The method we use:
- Measure first. Know the current numbers, so any change can be shown to have helped. Without a baseline, tuning is superstition.
- Find the actual constraint — CPU, memory, I/O or network. Tuning anything else changes nothing; see request profiling.
- Change one thing. Five changes at once means not knowing which helped, and one of them may be hurting.
- Measure again under realistic load. Idle benchmarks mislead.
- Record it — the value, the reason, the measured effect. A tuned system with no record becomes an untouchable system.
2. Limits That Bite in Production and Never in Testing
A specific class of problem: hard ceilings that are generous for a workstation and low for a busy server. They do not degrade gracefully — the system works, then abruptly refuses connections.
- File descriptors. Every connection and open file uses one. The per-process default is often far below what a busy server needs, and exhausting it produces confusing errors that look like anything but a limit.
- Connection backlog. How many pending connections the kernel holds while the application accepts them. Too small and a burst is refused at the door, invisibly.
- Ephemeral ports and connection-tracking tables, on hosts making many outbound connections, or behind a firewall doing stateful tracking.
- Process and thread limits, which cause failures that look like memory exhaustion and are not.
These are worth raising as a matter of course on a dedicated server. They cost nothing when unused and prevent a failure mode that is genuinely hard to diagnose under pressure.
3. Memory Behaviour
- Swap policy. A database whose memory is swapped out performs catastrophically; reducing the kernel's willingness to swap is standard for database hosts. But disabling swap entirely turns a slow system into a killed process, which is not obviously better — decide deliberately rather than by folklore.
- Overcommit, where a workload allocates far more than it uses, or where you would rather an allocation fail than have a process killed later.
- Huge pages for large-memory databases, where the reduction in page-table overhead is measurable. Transparent huge pages, by contrast, are commonly recommended against by database vendors — follow the vendor's guidance, not the general advice.
- Filesystem cache headroom. Leave the kernel room to cache; an application configured to use nearly all of RAM starves the cache and often ends up slower.
4. Storage and Network
- I/O scheduler matched to the device. What suits a spinning disk is unnecessary work on NVMe, where the simplest scheduler is usually best.
- Mount options — disabling access-time updates removes a write for every read, which is free performance on most workloads.
- Read-ahead, high for sequential workloads and low for random ones. Getting this backwards wastes a great deal of I/O.
- Congestion control and buffer sizes for high-bandwidth or long-distance links, where default buffers cap throughput well below the line rate.
- Keepalive and timeout settings on the reverse proxy, which govern how connections are reused and how quickly a failed upstream is noticed.
5. The Application Layer Is Where the Wins Are
Kernel tuning removes ceilings. It rarely makes a slow system fast. The changes that produce order-of-magnitude improvements are almost always higher up:
- Database configuration — memory allocation, shared buffers, work memory, checkpoint behaviour. A database at defaults on a dedicated server is typically using a fraction of the machine.
- Connection pooling. Opening a database connection per request is expensive; a pool sized by Little's Law rather than guessed is one of the highest-value changes available.
- Caching, at the right layer — query results, rendered fragments, static assets at the edge. And an eviction and invalidation policy decided deliberately, since a cache that serves stale data is worse than none.
- Worker and thread counts matched to cores and to whether the work is CPU-bound or waiting on I/O. More workers than the machine can run concurrently adds queueing, not throughput.
- Indexes and queries. One missing index routinely outweighs every kernel parameter on this page combined.
6. Make It Survive the Next Rebuild
Tuning applied at the command line lasts until reboot; tuning applied by hand lasts until the machine is rebuilt. Every value goes into configuration management with its comment, so it is reproducible and reviewable — see infrastructure as code. And every limit worth raising is worth monitoring, so you find out when you approach it again rather than when you hit it.
What You Get
- Before-and-after measurements, so the tuning is demonstrated rather than asserted.
- Kernel and service limits raised where they bind, each with a recorded reason.
- Database and connection-pool configuration matched to the hardware and the traffic.
- A caching strategy with an explicit invalidation policy.
- All of it in configuration management, and the relevant limits under monitoring.