Configuration Management Database (CMDB)
Back to Data Center Management · Asset Tagging · Rack Elevation Diagrams · Cable and Port Documentation · Service Offerings
A CMDB is a single source of truth that other tools and processes can reference — a record of your configuration items and, critically, of how they relate to one another. The term comes from ITIL, but you do not need to adopt ITIL to get the benefit, and the pages either side of this one are where most of its content comes from.
1. The Relationships Are the Point
This is the distinction that decides whether the exercise is worth anything. An inventory lists things. A CMDB says what depends on what.
An inventory answers "what do we have", which is useful and which asset tagging largely covers on its own. A CMDB answers the questions that have a therefore in them:
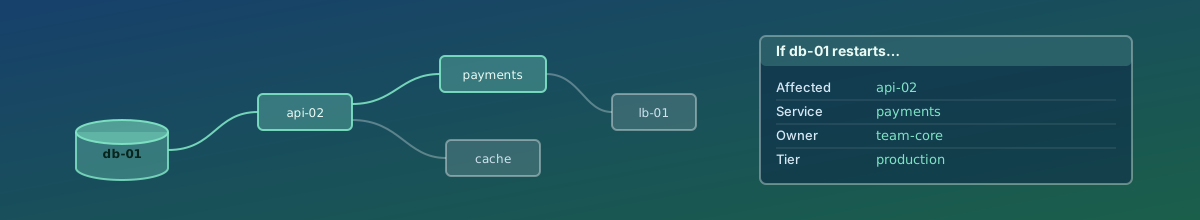
- If this database restarts, which services are affected, and who owns them?
- This alert is firing — what sits underneath it, and what sits on top?
- We are patching this host; whose change window does that belong in?
- This hardware goes end of life next quarter; what has to move, and in what order?
- Everything in scope for the audit — what is it, and prove the list is complete.
Every one of those is a graph traversal, not a lookup. A CMDB built as a flat list of servers with no relationships is an inventory with a more impressive name, and it will not answer any of them.
2. Scope It to the Questions You Actually Ask
The classic failure is the opposite of neglect: an attempt to model the entire estate in exhaustive detail, which produces a schema nobody can populate and a dataset that is stale before it is finished. The projects that fail are almost always the ambitious ones.
Each configuration item type should earn its place by answering a question somebody actually asks. A practical starting set:
| Layer | Typical items | Where it comes from |
|---|---|---|
| Physical | Servers, switches, PDUs, racks, sites | Asset register and rack elevations |
| Connectivity | Ports, links, circuits, addresses | Cable and port records, discovery |
| Logical | Virtual machines, containers, clusters, databases | Hypervisor, orchestrator and cloud APIs |
| Application | Deployed applications and their instances | Deployment pipeline |
| Service | What the business actually consumes, and who owns it | People — this layer cannot be discovered |
Start with two layers and the relationships between them, in one domain where somebody has a real question. Extend when the next question demands it. A small CMDB that is right is useful immediately; a comprehensive one that is half right is actively dangerous, because people act on it.
3. Name a System of Record for Every Attribute
A CMDB is usually not the place where facts are born. For each attribute, decide which system owns the truth and have the CMDB take its value from there.
- Discoverable facts should be discovered. Installed software, IP addresses, VM placement, cluster membership, firmware versions. Hand-maintaining anything a machine can report is how a CMDB becomes untrustworthy — the manual value is wrong within weeks and nobody knows which to believe.
- Some facts only people know. Business criticality, service ownership, which application a host belongs to, whether something is in audit scope. These need an owner and a review cadence, because nothing will ever discover them.
- Where two systems disagree, the rule must be written down and consistent. Unresolved conflicts are how trust erodes, and trust is the whole asset.
4. Accuracy Decays, So Measure It
A CMDB does not fail loudly. It drifts, quietly, and the damage is done precisely because people still rely on it: a change approved against stale dependencies takes down something nobody expected. An inaccurate CMDB is worse than no CMDB, because an absent one makes people go and check.
So treat accuracy as a measured property, not an aspiration:
- Reconcile against discovery on a schedule, and count the differences.
- Track the metrics that matter — items not seen by discovery for N days, items with no owner, relationships pointing at deleted items, attributes past their review date.
- Publish the figure. A known accuracy of 92 per cent is something people can reason about; an unknown accuracy gets treated as either perfect or worthless, and both are wrong.
- Make the update a step in the work. The same discipline as asset tagging, and it fails for the same reason when it is left as a follow-up task. Where provisioning is automated, the CMDB entry should be created by the same pipeline — see infrastructure as code.
5. What It Is Used For
- Change impact analysis. The primary return: before a change, the list of what depends on the thing being changed. This is what the illustration above shows.
- Incident triage. Which service an alerting host belongs to and who owns it, without asking around. Feeds root cause diagnosis and escalation.
- Audit scope and evidence. "Every system in scope, and evidence the list is complete" is a standard request in both ISO 27001 and SOC 2 work; the SOC 2 Evidence Helper covers how it is usually phrased.
- Lifecycle and end-of-life planning. What is approaching end of support, and what depends on it — which is what turns a list of dates into a plan.
- Capacity and licensing. What exists, where, and how much of it. See capacity trending and licensing.
6. Where It Sits Among the Others
The three preceding items each contribute a layer, and the CMDB is where they meet:
- Asset tagging provides identity — the stable key everything else references.
- Rack elevations provide location.
- Cable and port records provide connectivity.
- The CMDB adds the logical and service layers, and the relationships that let a question asked in business terms be answered in physical ones.
Which is also the order to build them in. A CMDB attempted before the physical inventory is trustworthy inherits every error underneath it.
How We Approach It
- Start from the questions. Collect the ones people actually ask and cannot currently answer. These determine the scope; nothing else should.
- Model only what those questions need — the item types, the attributes, and above all the relationship types.
- Name the system of record per attribute, and mark clearly which are discovered and which are human-owned.
- Connect discovery for everything a machine can report, and import the physical layers from the asset and cabling records.
- Populate one domain end to end, answer a real question with it, and let that earn the next phase.
- Set up reconciliation and the accuracy metrics, with the update step inside your change and provisioning processes.
What You Get
- A model scoped to the questions you need answered, with the relationship types that answer them — not a schema nobody can fill.
- Discovery feeding everything machine-knowable, and a named owner plus review cadence for everything else.
- A documented system of record per attribute, and a stated rule for conflicts.
- Change impact analysis that works, demonstrated against a real pending change.
- Reconciliation, accuracy metrics, and a published figure — so people know how far to trust it.
The measure of a CMDB is not how much it contains. It is whether someone about to make a change consults it, and whether they were right to.