Measure Before You Change Anything
Updated: October 5, 2026 (7531-10-15 in the Bulgarian calendar)
Back to Strategic Approach · End-to-End Profiling · Capacity Planning · Downtime Prevention · Service Offerings
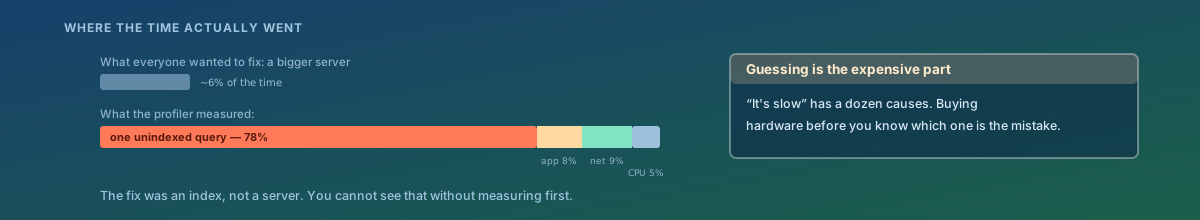
“It's slow” is a symptom with a dozen possible causes, and the expensive mistake is to start upgrading hardware before you know which one you have. The illustration above is the pattern in miniature: the fix was an index, and the server everyone wanted to buy would have moved the number by a few per cent. You cannot tell those two apart without measuring first — so we do.
1. Why Guessing Is the Expensive Part
A change made without a measurement is a bet, and the house edge is against you. There are many possible causes of a slow or failing system and usually only one that matters right now; a guess has to be lucky, and an unlucky guess costs more than the measurement would have.
- Hardware is the most expensive wrong answer. A bigger server is easy to authorise and feels like progress, which is exactly why it is reached for before the cause is known. When the bottleneck is a query, a lock, or a misconfigured pool, more hardware buys a small, temporary reprieve at permanent cost.
- A wrong fix hides the real one. Changing something that was not the problem adds a variable, muddies the next measurement, and occasionally makes things worse in a way that is now harder to diagnose.
- Intuition is trained on the last incident, not this one. Experienced engineers guess better than novices, but “better” still loses to a profiler. The whole value of measuring is that it is right about this system today.
2. What “Measure” Means Here
Measuring is not staring at a dashboard until something looks wrong. It is answering a specific question — where does the time or the resource actually go — with data from the running system.
- Profile the real path. For a slow request, that means end-to-end request profiling: following one real request through every layer and seeing where the milliseconds accumulate, rather than inferring it from aggregate graphs.
- Break the resource down. “High CPU” or “out of memory” is a starting point, not a cause — see the utilisation breakdown for turning a single number into the specific consumer behind it.
- Find the dominant query. A large share of application slowness lives in the database, and slow-query identification is often the shortest path from “it's slow” to a one-line fix.
- Reproduce under load, not in your head. Where the problem only appears at scale, a controlled load test produces the measurement that a quiet staging box never will.
3. Establish the Baseline First
You cannot tell whether a change helped if you never recorded what “before” was. A measurement taken only after the fix is just another guess wearing a number.
- Capture the before. The specific metric, under a specific load, at a specific time — the 95th-percentile latency, the peak hourly throughput, the error rate — written down before anything changes.
- Change one thing. One variable at a time, so the after-measurement attributes the effect to a cause. Two simultaneous changes and an improvement tells you nothing about which one did it.
- Measure the after the same way. Same metric, same load, same method — see before-and-after measurement. A change that cannot be shown to have helped should be treated as a change that did not.
4. It Applies Beyond Performance
The discipline is the same wherever the temptation is to act before you understand:
- Capacity planning. Provisioning against a measured trend and a known runway, not a feeling that you are “probably running low” — see capacity planning.
- Downtime investigations. During an incident the pull to “just restart it” is strongest and the evidence is most perishable. Downtime prevention depends on capturing what the system was doing before the state that fixed it is destroyed.
- Tuning. A parameter changed because it “should help” is a guess; the same change with a before and after is engineering.
5. When Not to Over-Measure
Measuring first is a discipline, not a ritual, and it has a cost too. The goal is a confident decision, not a perfect dataset.
- Match the measurement to the stake. A reversible, five-minute change on a low-traffic service does not need a week of profiling; a one-way migration or a hardware purchase does.
- Stop when the cause is clear. Once the profile points unambiguously at one dominant cost, more measurement is procrastination. Fix it, then measure the result.
- In a live incident, triage first. Restore service, but capture the evidence as you go — a snapshot of the logs, the metrics, the process state — so the real fix can follow the restart instead of being lost with it.
How We Approach It
- Turn the complaint into a question with a measurable answer: not “it's slow” but “where does the time in this request go?”
- Record the baseline — the metric, the load, the moment — before touching anything.
- Profile the real path until one dominant cause is unambiguous, rather than acting on the first plausible one.
- Change one thing, chosen because the measurement points at it.
- Measure the after the same way, and keep the change only if it is shown to have helped.
- Scale the effort to the stake — quick for the cheap and reversible, thorough for the expensive and permanent.
What You Get
- A named, measured cause before any money or downtime is spent on a fix.
- A recorded baseline, so “it's better now” is a number, not an impression.
- Changes made one at a time, each attributable to its effect.
- Fewer expensive wrong turns — the index found instead of the server bought.
The question worth asking before any infrastructure change: what measurement told us this was the problem, and what will tell us afterwards that we fixed it?